- Semiconductor BusinessHOME
- Products and Services of Macnica,Inc.
-
technical information

-
Events and Seminars
- Handling Manufacturer
- Support
- Inquiry
- Click here to purchase products
- Semiconductor business e-mail magazine registration


 Narrow down by specifying conditions
現在2229件がヒットしています。check
In recent years, NVIDIA has showcased numerous initiatives related to "Physical AI." Physical AI is an AI that understands input from cameras and sensors, as well as verbal instructions, and generates actions in the real world. It can be described as an evolution from traditional "recognizing AI" to "acting AI." Among these, autonomous driving is a prime example of a physical AI application, and it is also one of the most challenging areas to realize physical AI. The real world has countless traffic situations, and it is necessary to appropriately respond to edge cases such as pedestrians suddenly running into traffic, complex intersections, and construction zones.
However, conventional development methods require driving actual vehicles to collect data, making it difficult to adequately learn and evaluate edge cases due to cost and time constraints. To solve these problems, a system that continuously trains and evaluates AI models using simulations and synthetic data is essential. Therefore, NVIDIA is leading the development of autonomous driving in the era of physical AI by providing a comprehensive solution that includes AI models for autonomous driving, synthetic data generation, simulation, and an AI model training, evaluation, and deployment platform.
This article provides an overview of NVIDIA's suite of AI development solutions for autonomous driving.
*The information in this article is current as of the time of writing (August 2026). Please refer to the latest information regarding AI models, frameworks, etc.
Goals and scope of this article
goal
You will gain an overview of NVIDIA's AI development solutions for autonomous driving and be able to visualize how they can be applied to your own autonomous driving development and solution development.
subject
• People involved in autonomous driving development
・Those who feel limitations in data collection and verification, primarily through actual vehicle testing.
• Those interested in improving development efficiency through simulations and synthetic data.
・Those who want to learn about the latest autonomous driving AI models, such as the VLA (Vision Language Action) model.
Key technologies in the development of autonomous driving AI
Autonomous driving development is not as simple as "creating a smart AI model and being done with it." Because countless traffic situations exist in the real world, it is necessary to continuously run a cycle of collecting large amounts of data, training the AI, verifying it with simulations, and evaluating it in actual vehicles. In this chapter, in order to understand the overall picture, we will first look at the VLA model, which is the core of autonomous driving AI, then the development platform, and finally the challenges of data collection.
What is the VLA (Vision Language Action) model?
The ultimate goal of autonomous driving AI is to "understand the surrounding environment, take human intentions into account, and select safe driving actions." However, conventional AI processes recognition, prediction, and control separately, which limits its ability to handle complex situations. The VLA model is attracting attention as a next-generation architecture that solves these problems.
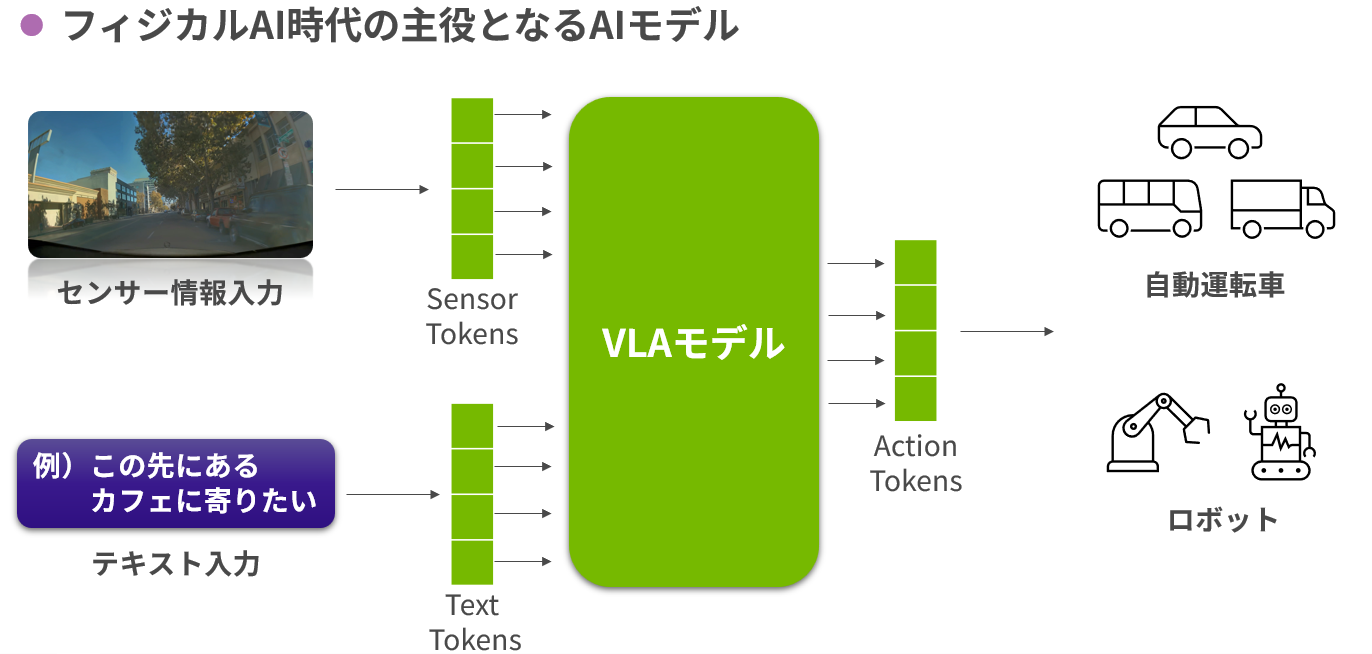
The following diagram illustrates the input and output of the VLA model. It receives sensor information such as cameras and text instructions from the user as input, and outputs the actions that the autonomous vehicle or robot should take.
The evolution of autonomous driving software
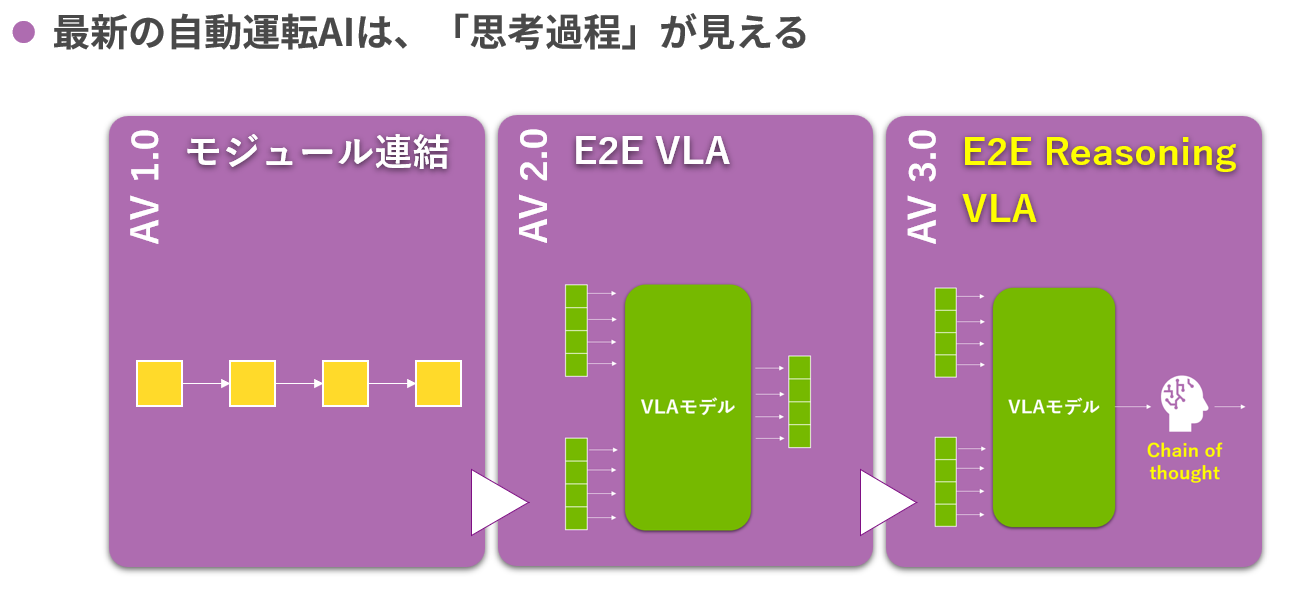
NVIDIA categorizes the evolution of its autonomous driving software into three generations.
With the advent of VLA, the design philosophy of autonomous driving software itself has also changed significantly. In the latest AV (Autonomous Vehicles) 3.0 generation, a major feature is that AI not only outputs driving operations but also reveals the thought process behind "why that decision was made." As a result, autonomous driving AI has evolved from a mere black Box into a verifiable system. Developers can improve models while analyzing the AI's decision-making rationale, thereby enhancing debugging efficiency and the accuracy of safety evaluations. Additionally, rare cases that were previously difficult to handle can now be continuously learned and improved by monitoring the AI's decision-making process, leading to faster autonomous driving development.
|
generation |
name |
Speciallong |
|
AV 1.0 |
Classical Modular Stack |
Recognition, prediction, planning, and control Conventional construction using individual modules |
|
AV 2.0 |
End-to-End VLA |
From sensor input to VLA and then to operating output, it's a seamless, end-to-end process. |
|
AV 3.0 |
End-to-End Reasoning VLA |
Possessing the reasoning ability to explain the basis for one's decisions. |
The "three computers" necessary for developing physical AI
Autonomous driving cannot be achieved simply by creating a high-performance VLA model. To train the model, verify it through simulation, and ultimately operate it on a vehicle, a computing infrastructure is needed to support everything from development to operation. Therefore, NVIDIA is proposing the concept of "three computers" to support physical AI development.
|
|
role |
computer |
|
① Learning |
Supercomputers responsible for large-scale training of AI models |
NVIDIA DGX™ / NVIDIA HGX™ |
|
② Verification |
Simulation execution and synthetic data generation |
NVIDIA RTX PRO™ Server / NVIDIA RTX PRO™ Workstation |
|
③ Execution |
Performing in-vehicle reasoning as the "brain" of an autonomous vehicle. |
AGX (In autonomous driving, this refers to NVIDIA DRIVE AGX™) |
The "barrier to data collection"
The biggest challenge in developing physical AI is data collection. Even with a powerful computing infrastructure, AI cannot become smart without data to use for training. Autonomous driving, in particular, requires training on a large number of edge cases, but collecting these solely from the real world is extremely difficult. This is where we face the "data collection wall." There are three ways to acquire data, each with its own advantages and disadvantages.
• Real-world data: High quality but limited in quantity and cost, and constrained by the availability of actual equipment and time.
Webdata: Large quantities and low cost, but quality is inconsistent, and the desired data may not always be available.
• Simulation data: Theoretically, it can scale infinitely and generate any data, but it requires GPU resources.
NVIDIA's AI development solutions for autonomous driving aim to overcome this "data collection barrier" through simulation and synthetic data generation.
An overview of NVIDIA's autonomous driving AI development solutions
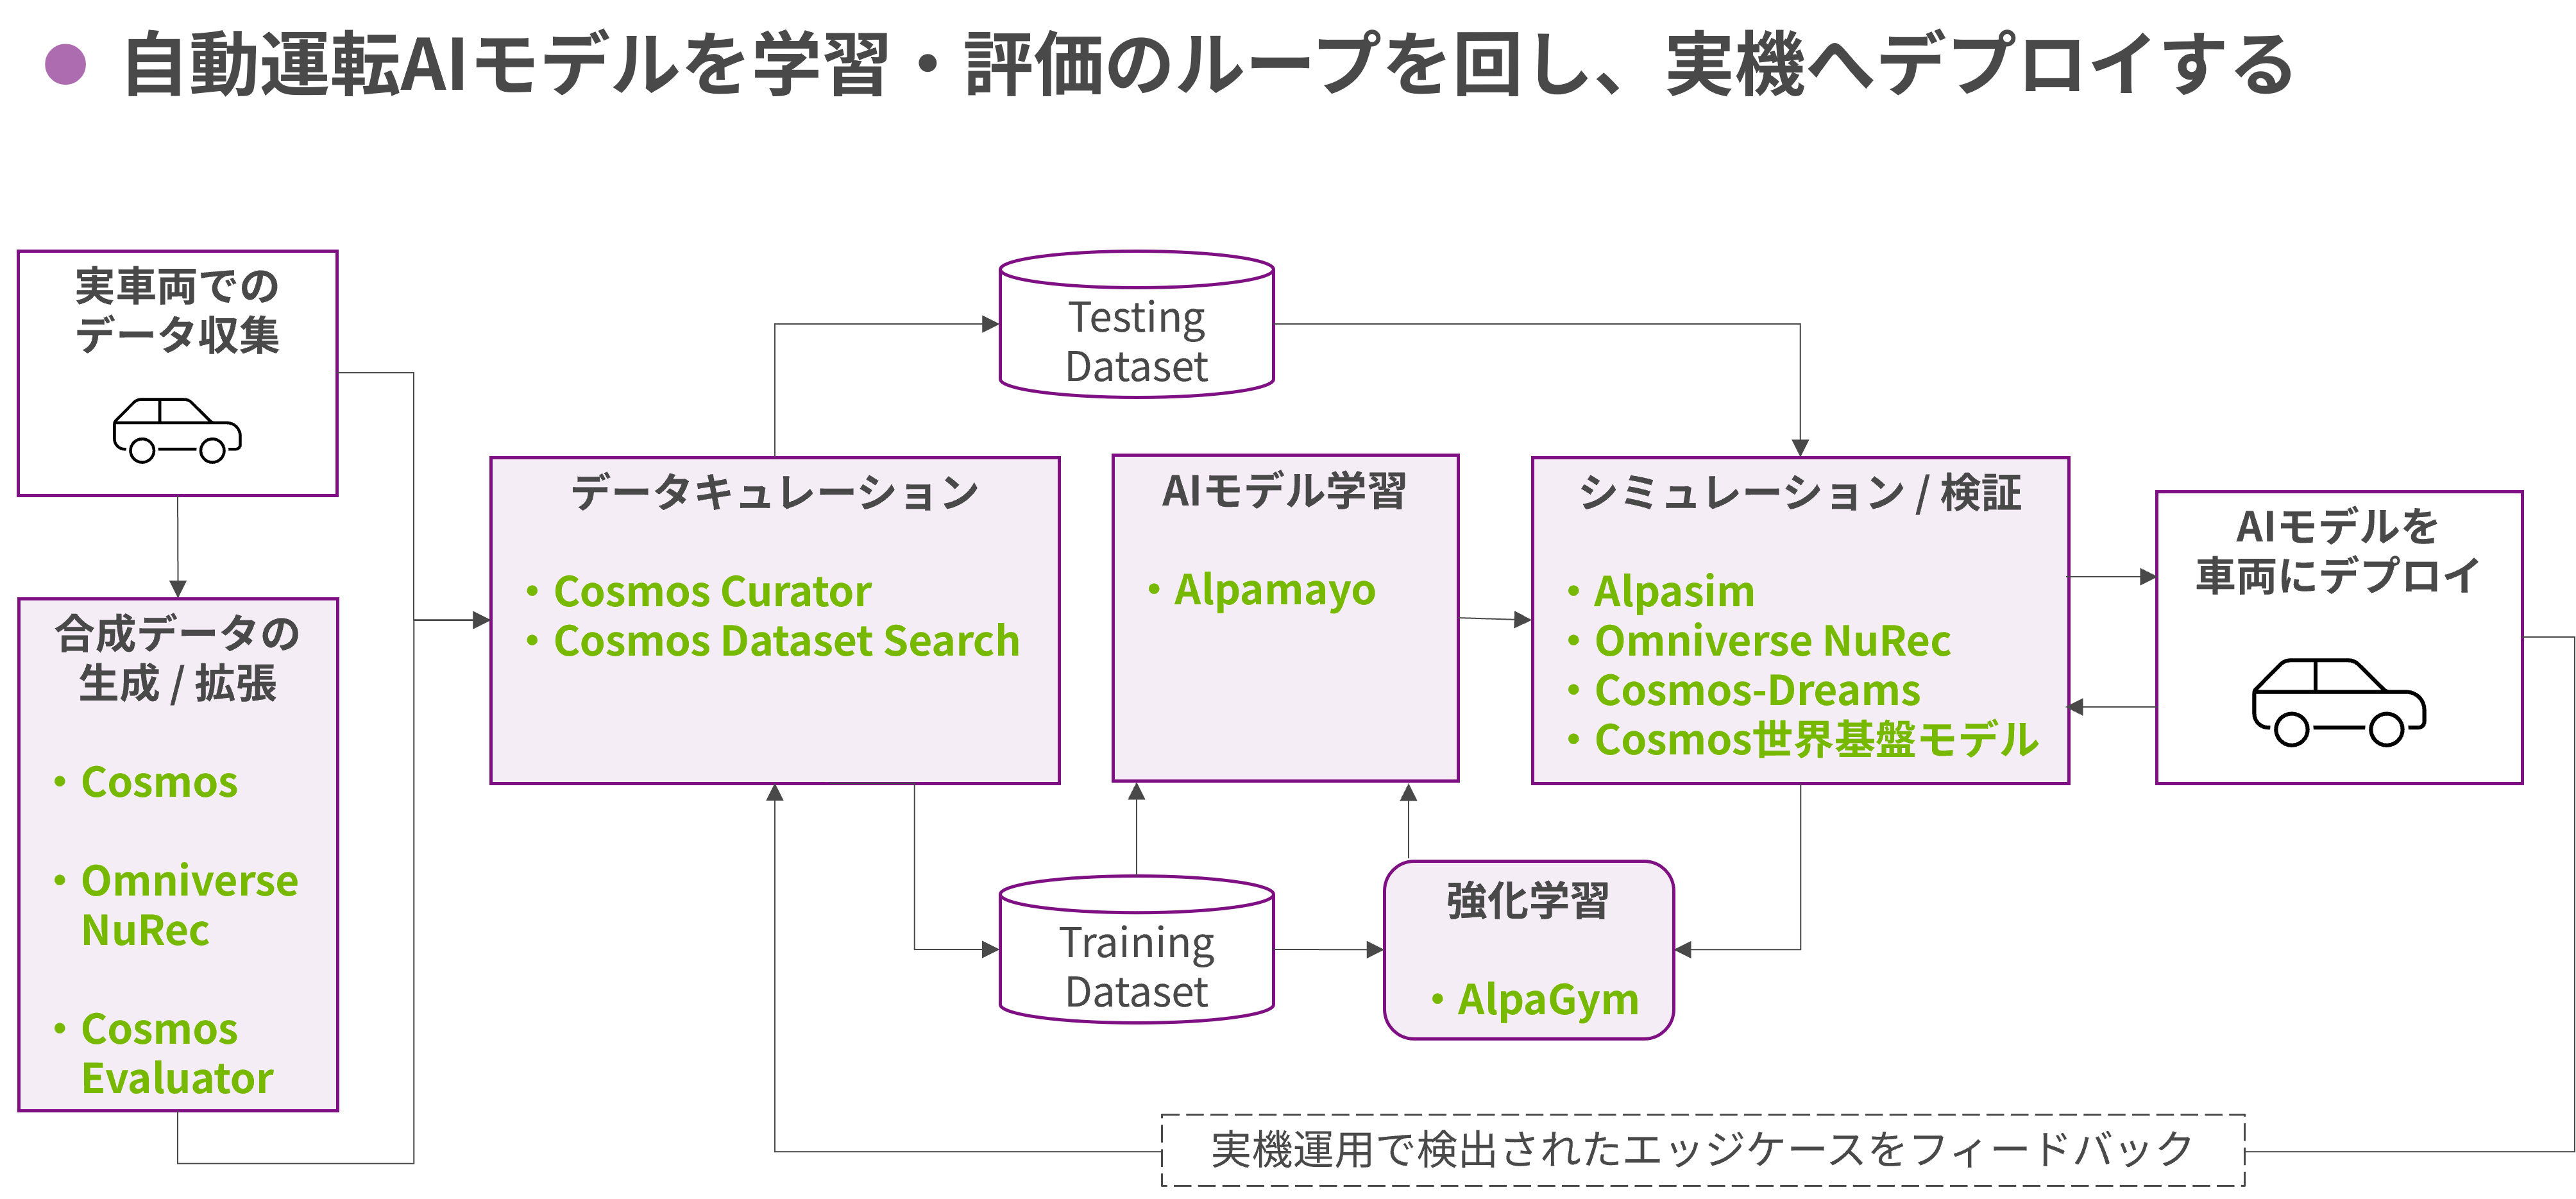
In developing AI for autonomous driving, it's crucial to continuously cycle through data collection, learning, evaluation, and real-world testing. NVIDIA provides solutions to support this entire development cycle.
The following diagram illustrates the overall picture of NVIDIA's autonomous driving AI development solutions.
This article will focus on the main solutions highlighted in green, explaining their respective roles and features.
NVIDIA Cosmos: Training data generation / augmentation and data processing / search / evaluation
NVIDIA Cosmos™ is a platform centered around World Foundation Models for physical AI. It provides a suite of open models for video generation and understanding, along with workflows for building training datasets using these models. Its aim is to supplement areas where real-world data alone is insufficient, thereby improving the comprehensiveness, diversity, and quality of datasets. Cosmos consists of multiple models and tools.
Cosmos World Foundation Model
Cosmos can address the data shortage challenge in autonomous driving AI development. However, this challenge can be broadly categorized into two patterns.
① This is a case where the necessary learning scenario simply does not exist.
For example, there are scenarios in the real world where we cannot collect enough data, such as edge cases that could lead to serious accidents or unique traffic conditions.
② This is a case where data exists, but the variety and quality are insufficient.
For example, while there may be ample data on driving conditions in clear weather, there might be insufficient data for rainy weather, nighttime conditions, or snowy conditions, or the images generated by simulations might be unnatural compared to the real world.
Cosmos offers models with different roles to address these challenges.
・ Cosmos 3: Creating insufficient scenarios or the world itself
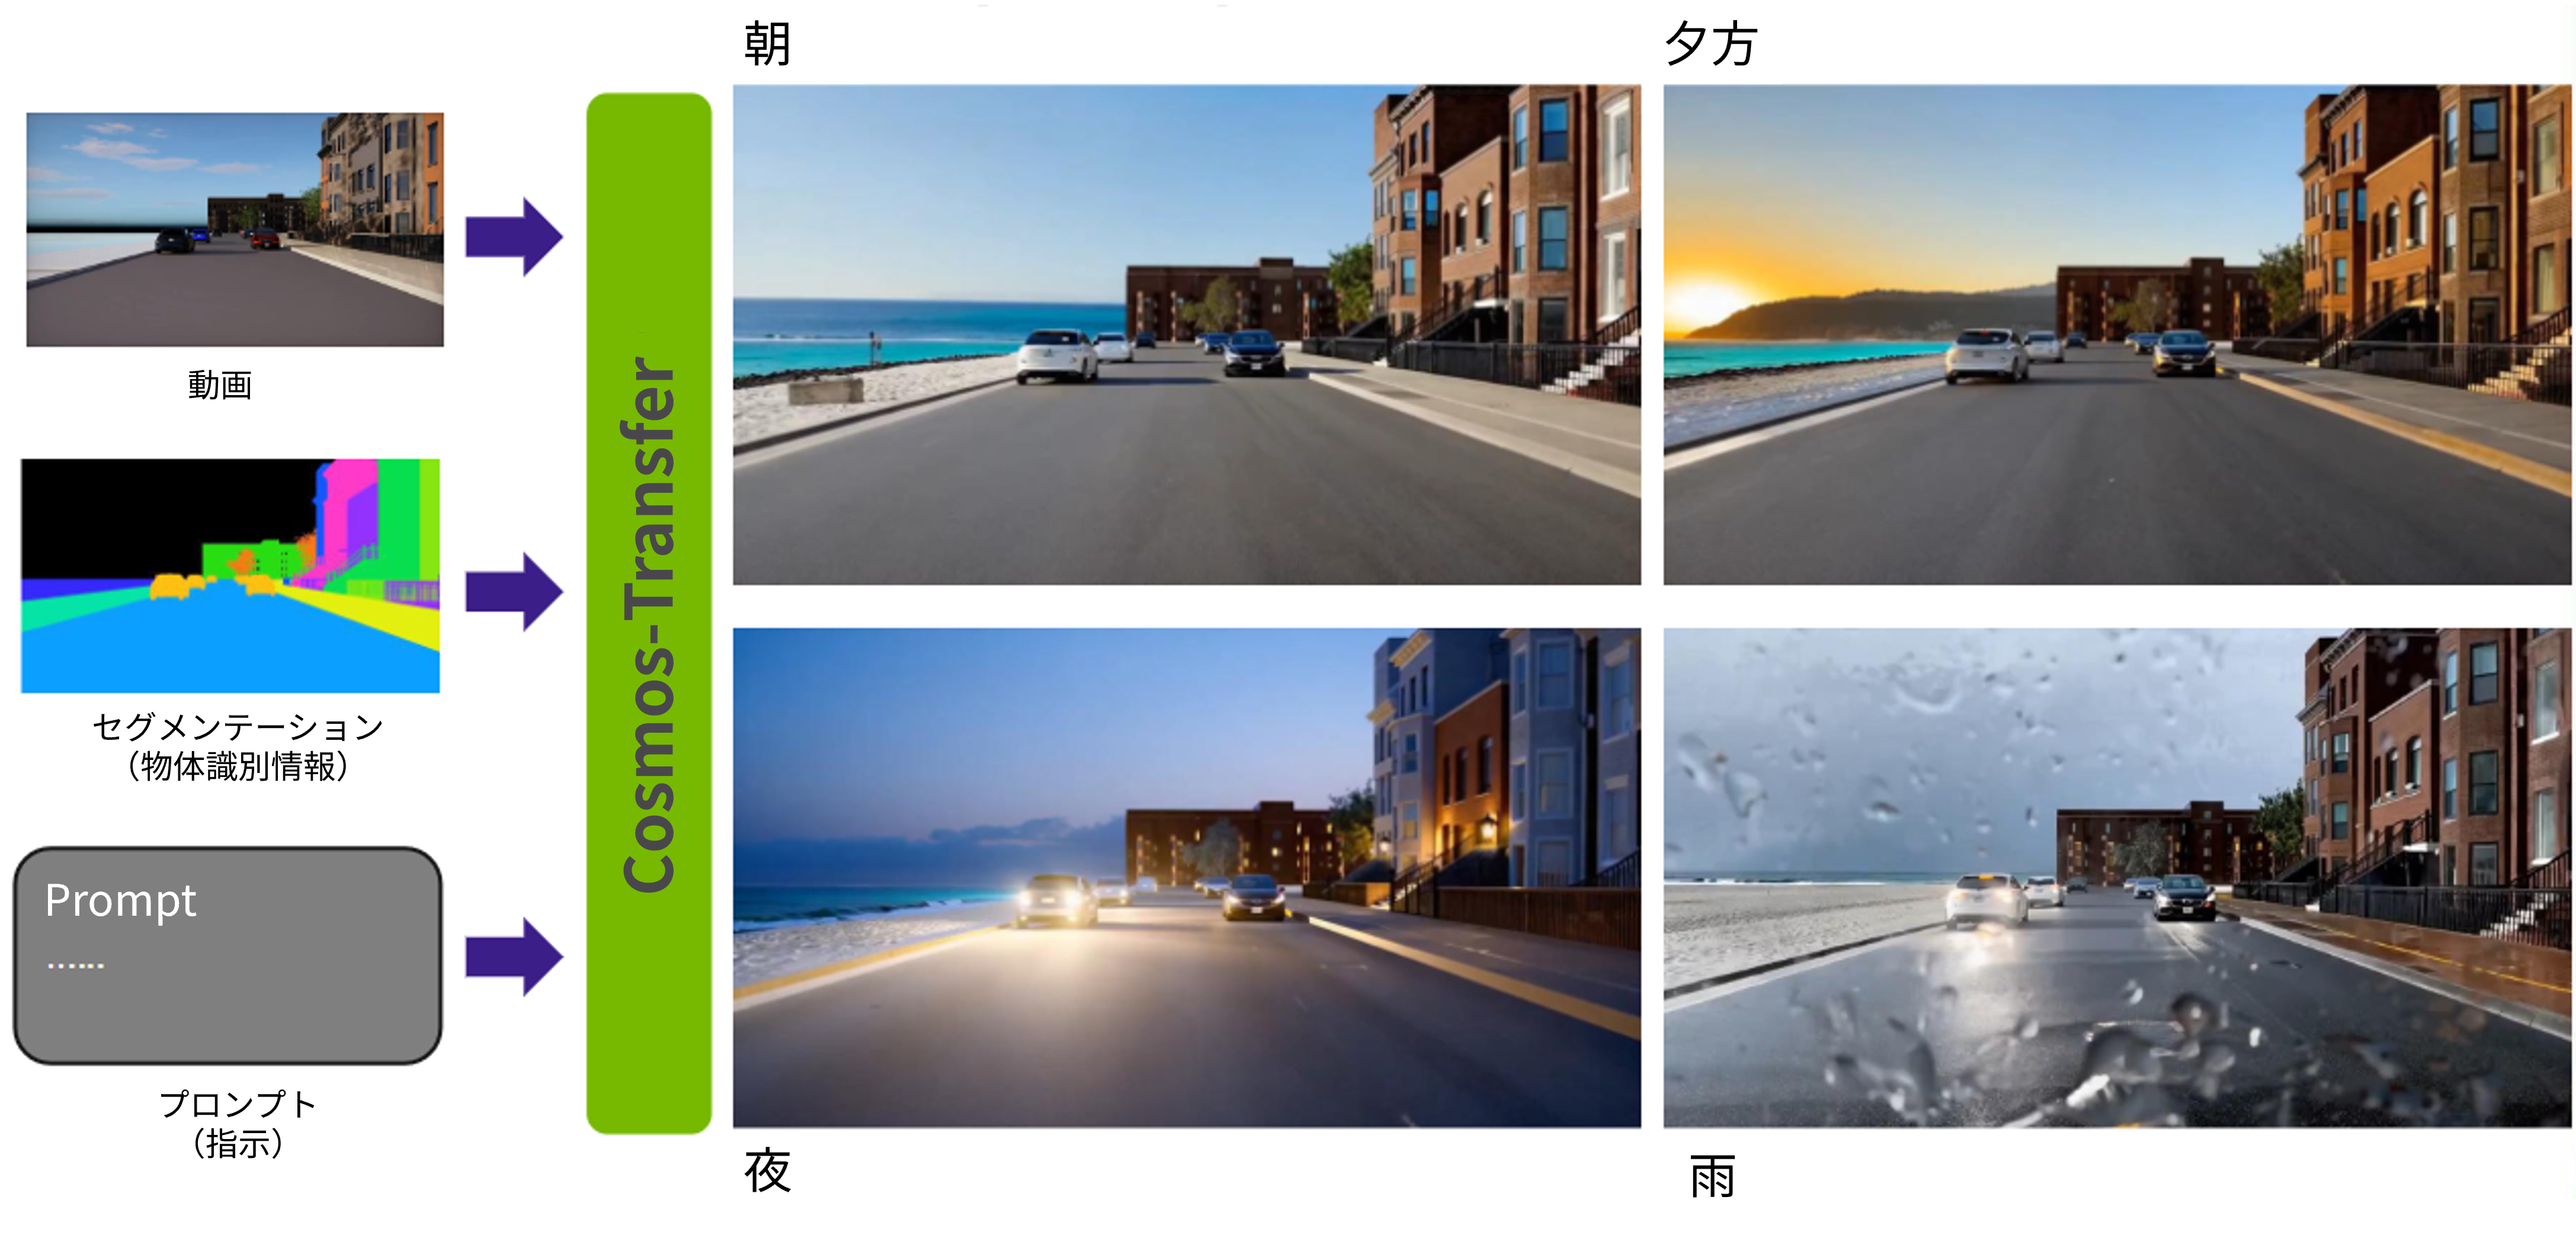
・ Cosmos-Transfer 2.5: Expanding training data by transforming the conditions of existing data and photorealisticizing simulation images.
The following explains each role.
◆Cosmos 3
In the real world, there are many cases where sufficient training data is not available.
for example,
- Scenario with a low frequency of occurrence
This includes complex traffic conditions, etc.
Cosmos 3 is a World Foundation Model designed to generate such insufficient scenarios.
As an omni-channel model that handles text, images, videos, audio, and actions, it enables world understanding, world creation, and action generation.
It has the following features:
• Multiple uses for one model:
World Understanding / World Generation / World Action /
Multimodal simulation can be implemented with a single model.
・ Two size options available:
NVIDIA Cosmos 3 Nano (16B) and NVIDIA Cosmos 3 Super (64B)
• Open access:
Open weights, training recipes, and benchmarks are available on Hugging Face and GitHub. Deployable on NVIDIA NIM™ Microservices.
As a global model:
It supports multiple frame rates (10-30) and multiple resolutions (256p/480p/720p), Maximum 30 seconds Supports long-scale generation
It is also possible to generate worlds with sound.
◆Cosmos-Transfer 2.5
Cosmos-Transfer 2.5 is a model that transforms existing video footage into different conditions or representations. By expanding the training data, you can increase the diversity of the dataset by transforming sunny days into rainy days, or daytime into nighttime.
Furthermore, it can be used to convert simulation footage, which is widely used in autonomous driving development, into photorealistic footage that closely resembles real-world images. This allows the large amount of data generated by simulations to be used for training as data that is closer to the real world.
Cosmos data processing, search, and evaluation tools
Data processing, search, and evaluation tools incorporating Cosmos's AI models are also available.
|
component |
role |
|
Cosmos Curator |
The massive amount of video data is processed at high speed using a GPU, and the dataset is organized. |
|
Cosmos Dataset Search |
Search any scene within a dataset quickly using natural language or video. |
|
Cosmos Evaluator |
Automating the evaluation of videos generated by AI |
NVIDIA Cosmos-Dreams: A global model for autonomous driving simulations
NVIDIA Cosmos-Dreams is a world model within the NVIDIA Cosmos family that sequentially generates future scenes based on vehicle driving conditions. It takes an initial RGB frame, text prompts, HD map images, and trajectory poses as input and generates multi-camera photorealistic video in real time.
In the context of closed-loop verification combined with Alpamayo and AlpaSim, which will be discussed later, the configuration can be organized as follows: Alpamayo functions as the policy model, AlpaSim as the simulation runtime, and Cosmos-Dreams as the world model. In this configuration, based on state updates from AlpaSim, Cosmos-Dreams generates the next synthesized camera image, and the behavior of the model is continuously evaluated.
Domain-specific post-training
Cosmos can be tuned to domain-specific models using LoRA, DMD2, supervised fine-tuning (SFT), and reinforcement learning (RL).
It can be applied not only to autonomous driving, but also to a wide range of fields such as robotics, medicine, and manufacturing.
Effects of introducing Cosmos
• Reduced data collection costs: Cosmos 3 and Cosmos-Transfer 2.5 allow you to supplement insufficient edge cases and data diversity with synthetic data, without relying on actual vehicle testing.
• Improved development speed: Cosmos Curator reduces the time required to process 20 million hours of video from the equivalent of 3.4yearsin anunoptimized environment with 2,000CPUs to 40daysin anNVIDIA Hopper GPU environment.
• Faster data exploration: Cosmos Dataset Search instantly searches for target scenarios from hundreds of millions of videos, enabling a data discovery loop approximately 20 times faster than conventional methods.
• Automated evaluation: Cosmos Evaluator can evaluate 1,500 videos per 3 hours using 30 NVIDIA A100s, eliminating the variability of human judgment.
• Simulation verification using a global model: Cosmos-Dreams can sequentially generate future scenes according to the vehicle's driving conditions, making it promising for verifying the behavior of autonomous driving AI while generating future scenes.
NVIDIA Omniverse NuRec: Simulation space reconstruction using real-world vehicle data
NVIDIA Omniverse™ NuRec is a suite of models and services that take sensor data (camera /LiDAR data, etc.) acquired from actual vehicle testing and reconstruct and render a 3D simulation environment. Its greatest feature is that it can transform a once-captured driving scene into a "reusable 3D simulation environment" that can be reproduced and verified repeatedly under different conditions. Sensor information acquired from actual vehicle testing is converted into NCore format (NVIDIA 's standardized format for sensor data recording), and then reconstructed and rendered to depict the simulation space.
While the aforementioned Cosmos-Dreams is a world model that generates future camera footage based on conditional input, NuRec is characterized by its ability to reconstruct existing driving scenes as a 3D simulation environment, starting from sensor data acquired in the real world. In other words, while Cosmos-Dreams plays the role of "generating future scenes," NuRec plays the role of "converting already captured real-world scenes into a reusable environment."
Main function
- Generation of new trajectories and sensor viewpoints: Within the reconstructed space, it is possible to change the sensor's FOV and position, or render viewpoints that are shifted laterally from the original trajectory.
- Scenario expansion: Assets can be inserted into the simulation space later to create new scenarios.
•Fixer: A model that corrects artifacts and blurs that occur during reconstruction.
•Harmonizer: A model that enhances the harmony and temporal consistency of lighting, shadows, and appearance in reconstructed and rendered frames.
•Asset Harvester: A model/workflow that converts actors and objects in real-world data into 3D assets, making them easier to reuse in other scenes.
•InstantNuRec: A model that outputs 3D Gaussian Splatting (3DGS) scenes from multi-view image input.
•Agent SkillsIntegration: Agent Skills (nurec-skills) for NuRec are available and can be used to support NuRec-related workflows with AI agents.
Integration with simulation frameworks
NuRec integrates with NVIDIA's AlpaSim simulation framework, as well as toolchains from leading simulation partners such as CARLA and Foretellix.
NVIDIA Alpamayo: Open VLA models and toolset for autonomous driving
NVIDIA Alpamayo is a family of open VLA models, simulation frameworks, reinforcement learning infrastructure, and physical AI datasets for autonomous driving, which can be used as a starting point for autonomous driving AI development.
Alpamayo's model lineup is as follows:
|
Item |
NVIDIA Alpamayo 1 Nano |
NVIDIA Alpamayo 1.5 Nano |
NVIDIA Alpamayo 2 Super |
|
Positioning |
World's first open inference VLA (for AV). |
Steering, dialogue, and learning from company data become possible. |
Largest-scale open AV inference VLA-based model |
|
release |
November 2025 |
March 2026 |
August 2026 |
|
parameter |
10B |
10B |
34B |
|
backbone |
Cosmos-Reason 2 |
Cosmos-Reason 2 |
Cosmos 3 Reasoner |
|
⼊⼒ |
Front-facing 4 cameras |
Front 1-4 cameras |
Up to 7 cameras (360-degree coverage) |
|
Output |
Orbital plan up to 6.4 seconds ahead |
Orbital plan up to 6.4 seconds ahead |
Orbital plan up to 6.4 seconds ahead |
|
study |
SFT only |
SFT |
SFT |
The ability to explain the reasoning behind a particular driving decision embodies the key features of the AV 3.0 generation.
Furthermore, Alpamayo is pre-trained on large-scale and diverse data. Companies using Alpamayo can build upon this foundation by adding enhanced reasoning for specific purposes and handling rare cases.
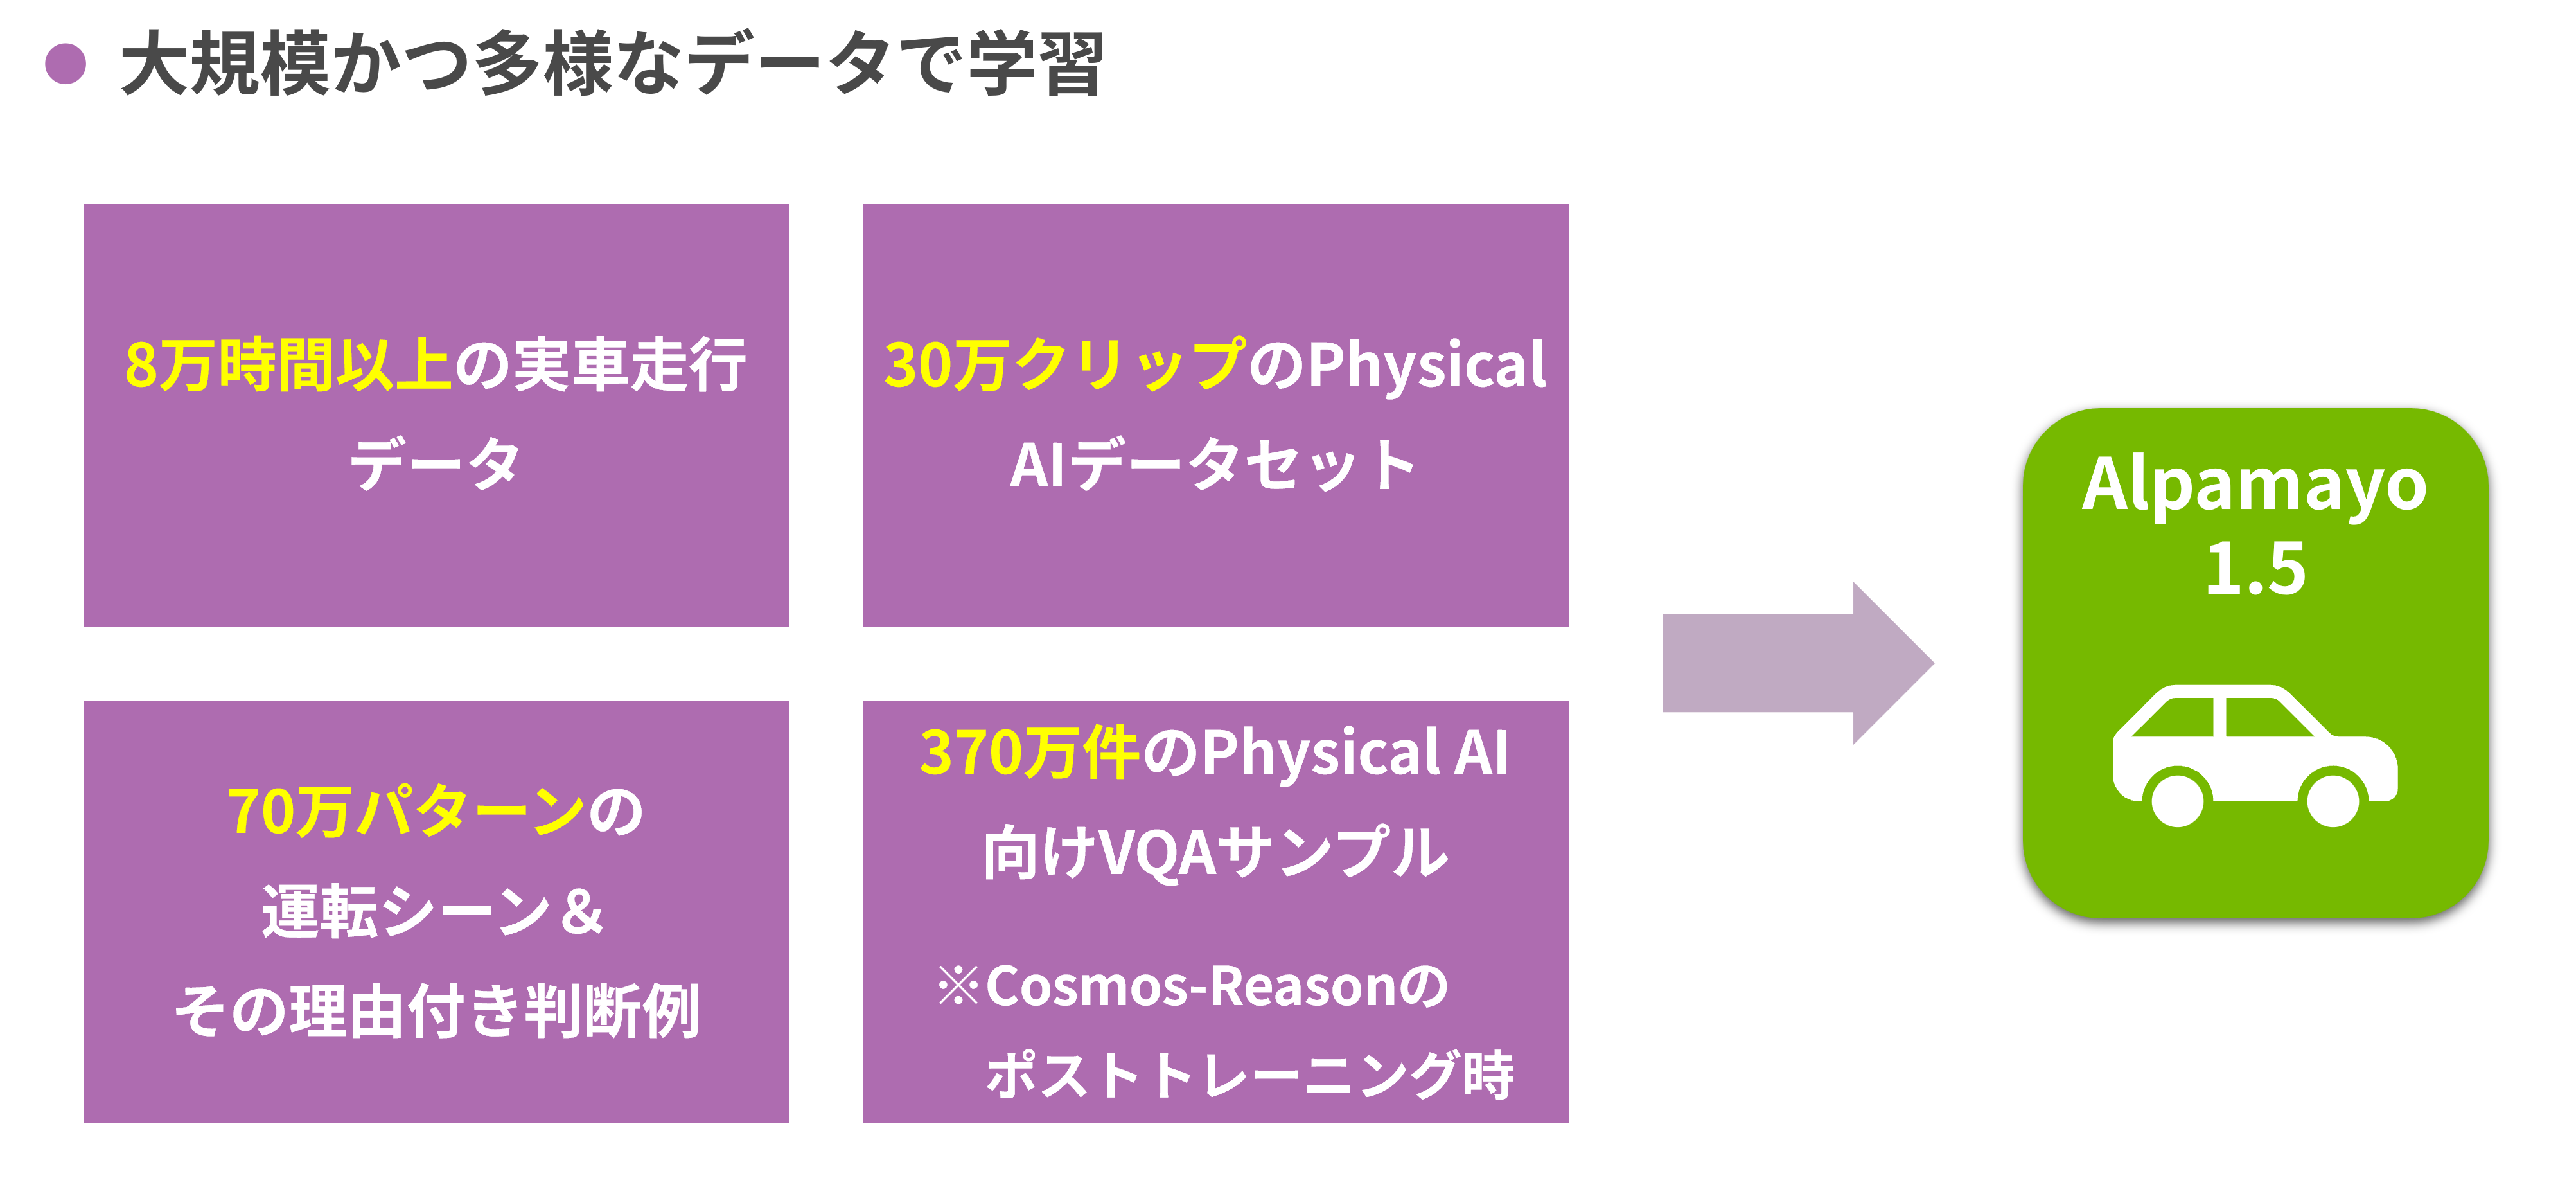
Alpamayo Family
◆NVIDIA AlpaSim: An open-source closed-loop AV simulation framework
This is a Python-based closed-loop simulator that runs policy models (AI responsible for driving) like Alpamayo in a simulated space and evaluates their behavior. Unlike open-loop verification, which plays back recorded video, the model's manipulation is reflected in the scene, and the results are returned as the next input, allowing for evaluation of strategies under interactions similar to those on real roads.
◆NVIDIA AlpaGym: Closed-loop reinforcement learning infrastructure
AlpaGym is a framework that uses AlpaSim as its execution engine to train Alpamayo's driving strategies through reinforcement learning. It runs the model on AlpaSim, uses the results to update the strategy as a reward, and then runs the model again with that updated strategy, repeating this loop at high throughput.
◆PhysicalAI-Autonomous-Vehicles: Large-scale, diverse multi-sensor datasets for physical AI
PhysicalAI-Autonomous-Vehicles is a large and diverse open-source dataset of vehicle data.
• Over 1,700 hours of running data
- Over 300,000 clips of multi-camera + LiDAR data (20 seconds each), and over 160,000 clips of radar data.
• Geographic coverage spanning over 2,500 cities in 25 countries (please note that Japan is not included).
Contact Us
We hope this article will help you gain a deeper understanding of NVIDIA's AI development solutions for autonomous driving.
Macnica can provide support for the implementation of NVIDIA's autonomous driving AI development solutions, as well as assistance with selecting and supporting hardware such as GPU cards and GPU workstations.
If you are considering implementation, please feel free to contact us using the information below.