- Semiconductor BusinessHOME
- Products and Services of Macnica,Inc.
-
technical information

-
Events and Seminars
- Handling Manufacturer
- Support
- Inquiry
- Click here to purchase products
- Semiconductor business e-mail magazine registration


 Narrow down by specifying conditions
現在2232件がヒットしています。check
This article describes our efforts to create a Robot Policy for SO-ARM by further training a Cosmos3 Nano using our own collected SO-ARM robot operation data, based on the post-training recipe for NVIDIA Cosmos™ 3 Robot Policy published by NVIDIA.
This article does not provide a detailed explanation of implementation or learning settings, but rather aims to help you understand the overall picture of what Cosmos 3 is, what Robot Policy is, and how to create and apply a custom Robot Policy to your own robot.
What is NVIDIA Cosmos 3?
Cosmos 3 is a foundational model for physical AI released by NVIDIA. While typical generative AI is primarily used to generate text and images, Cosmos 3 can integrate and handle multiple types of information, including images, videos, audio, and actions.
Therefore, Cosmos 3 can be used as a foundation for a variety of physical AI applications.
- Models that understand images and videos
• A model for controlling robots (Robot Policy)
• Models that predict future states
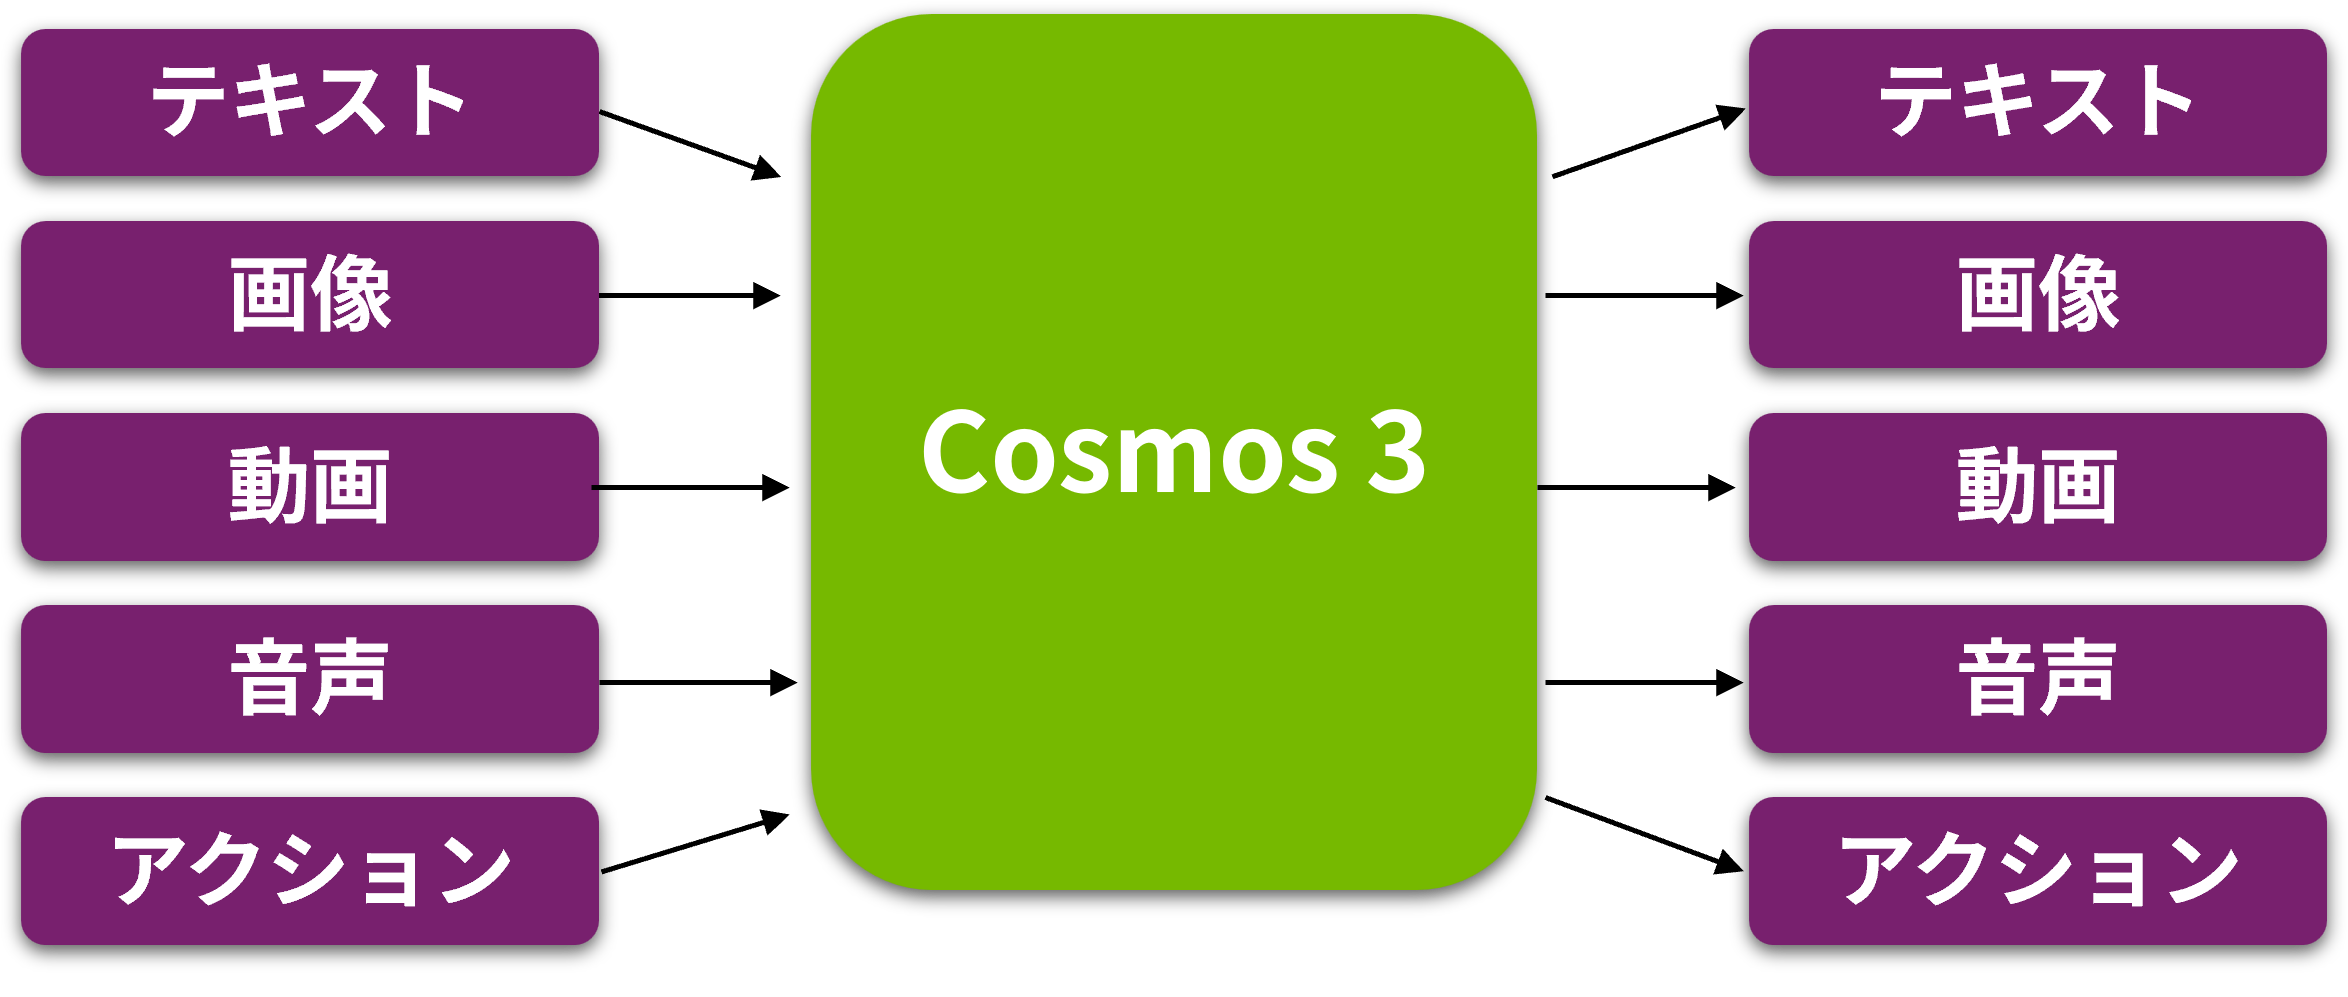
A key feature of Cosmos 3 is its ability to not only understand the current state of the world but also predict "what will happen next." This predictive capability makes it a highly compatible foundational model for physical AI that operates in the real world, such as robot control and autonomous driving.
The Robot Policy we'll be discussing is a model specifically designed for robot control. By training it with images, current joint states, operation instructions, and actual movements collected from a particular robot, you can create a Robot Policy tailored to that robot. By post-training (additional learning) Cosmos 3 with data suited to your application, you can build a dedicated derivative model.
Cosmos 3 is "the foundation for physical AI that can predict the future," andRobot Policy is a specialized model for robot control built upon that foundation.
Reference: Cosmos 3
What is the Robot Policy in Cosmos 3?
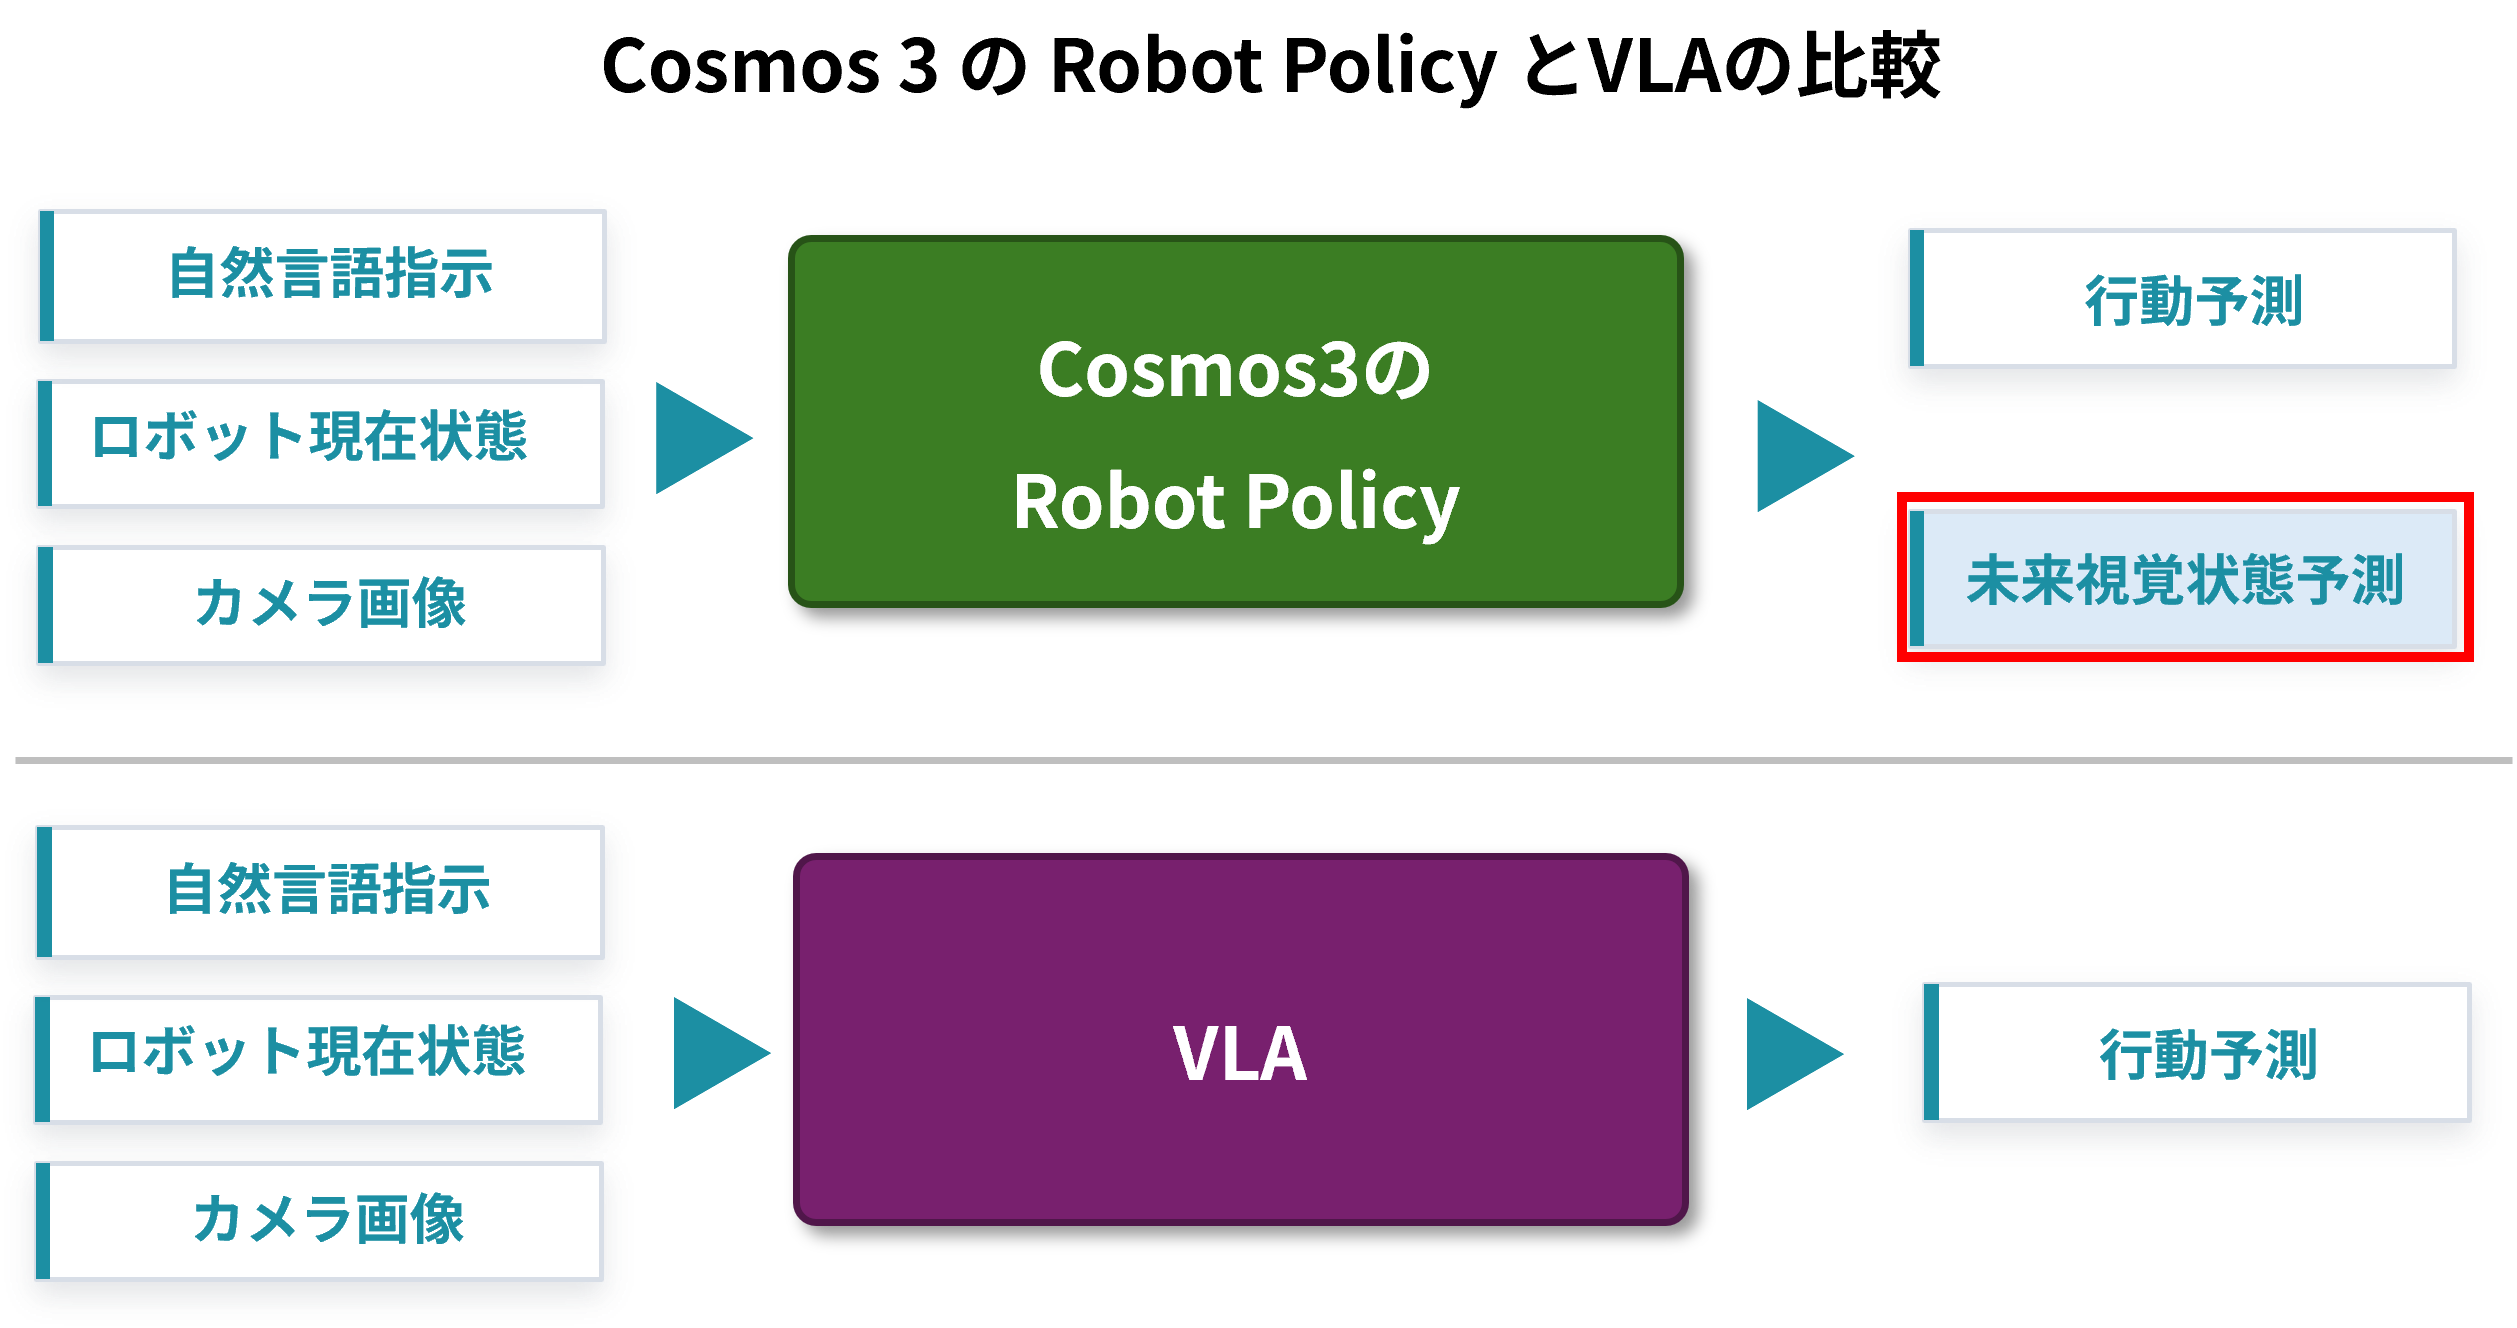
In recent years, VLA (Vision-Language-Action) has become widely used as AI for robot control. VLA is a model that directly generates robot movements from images and language instructions.
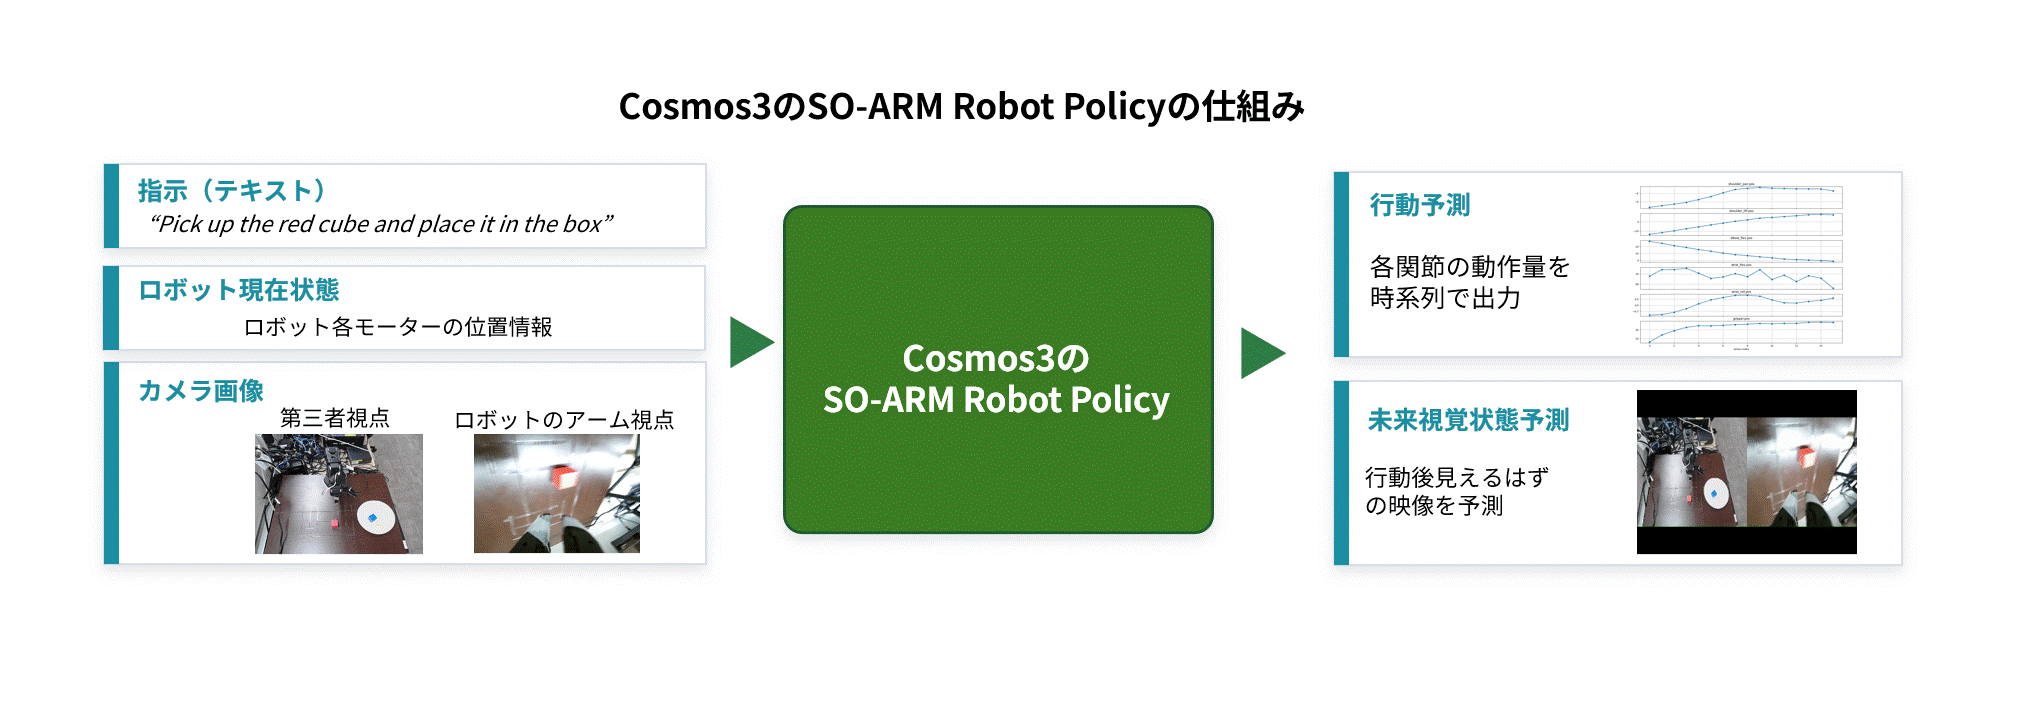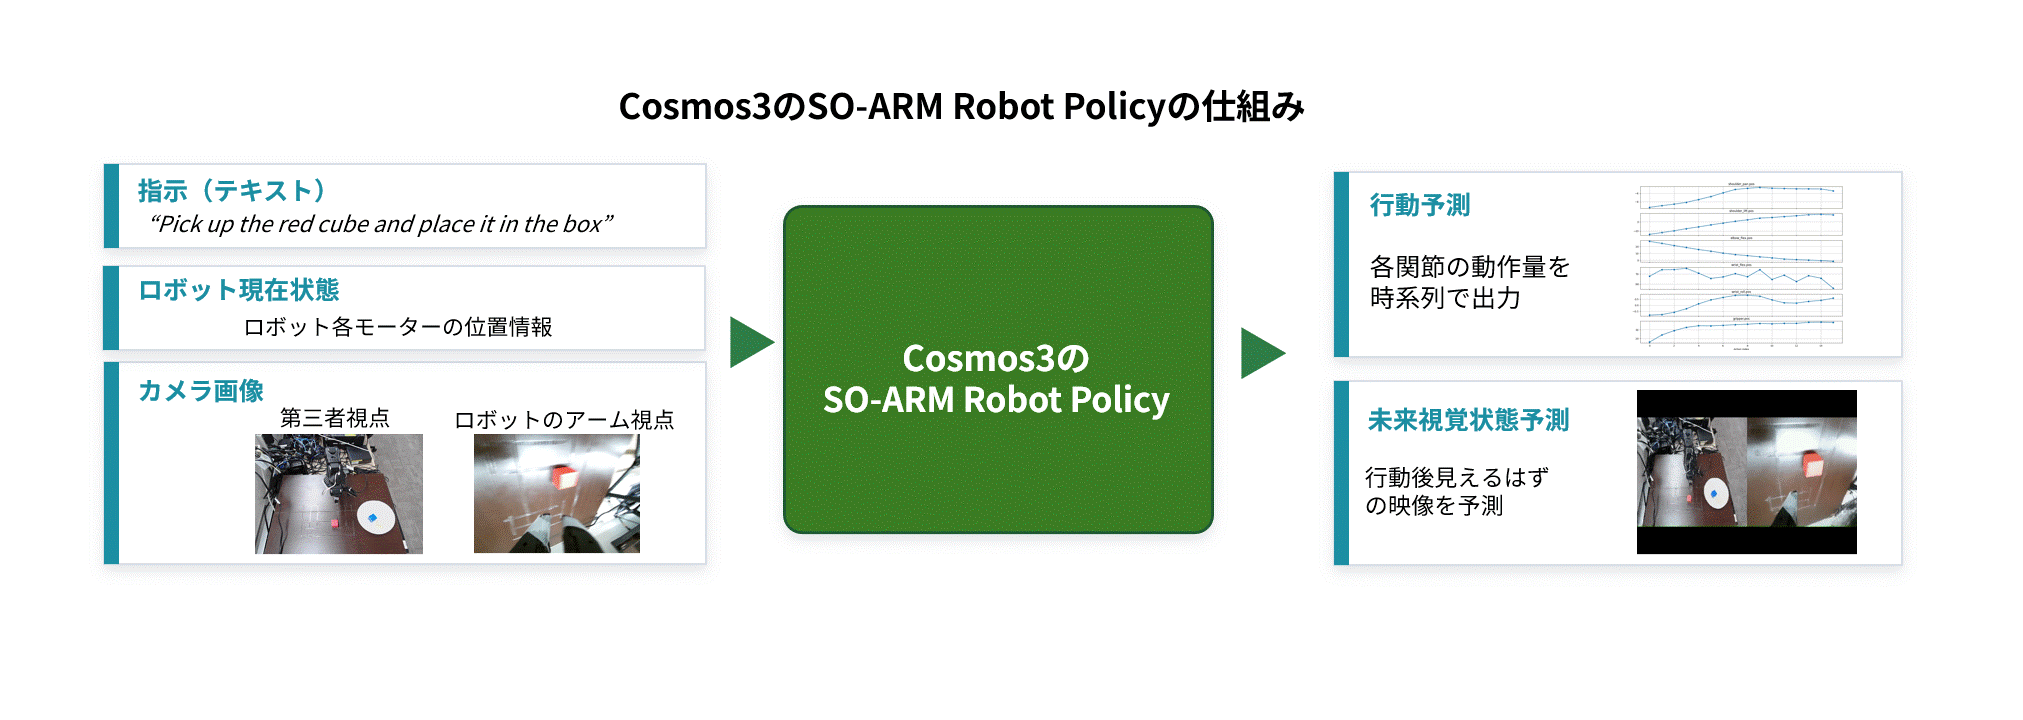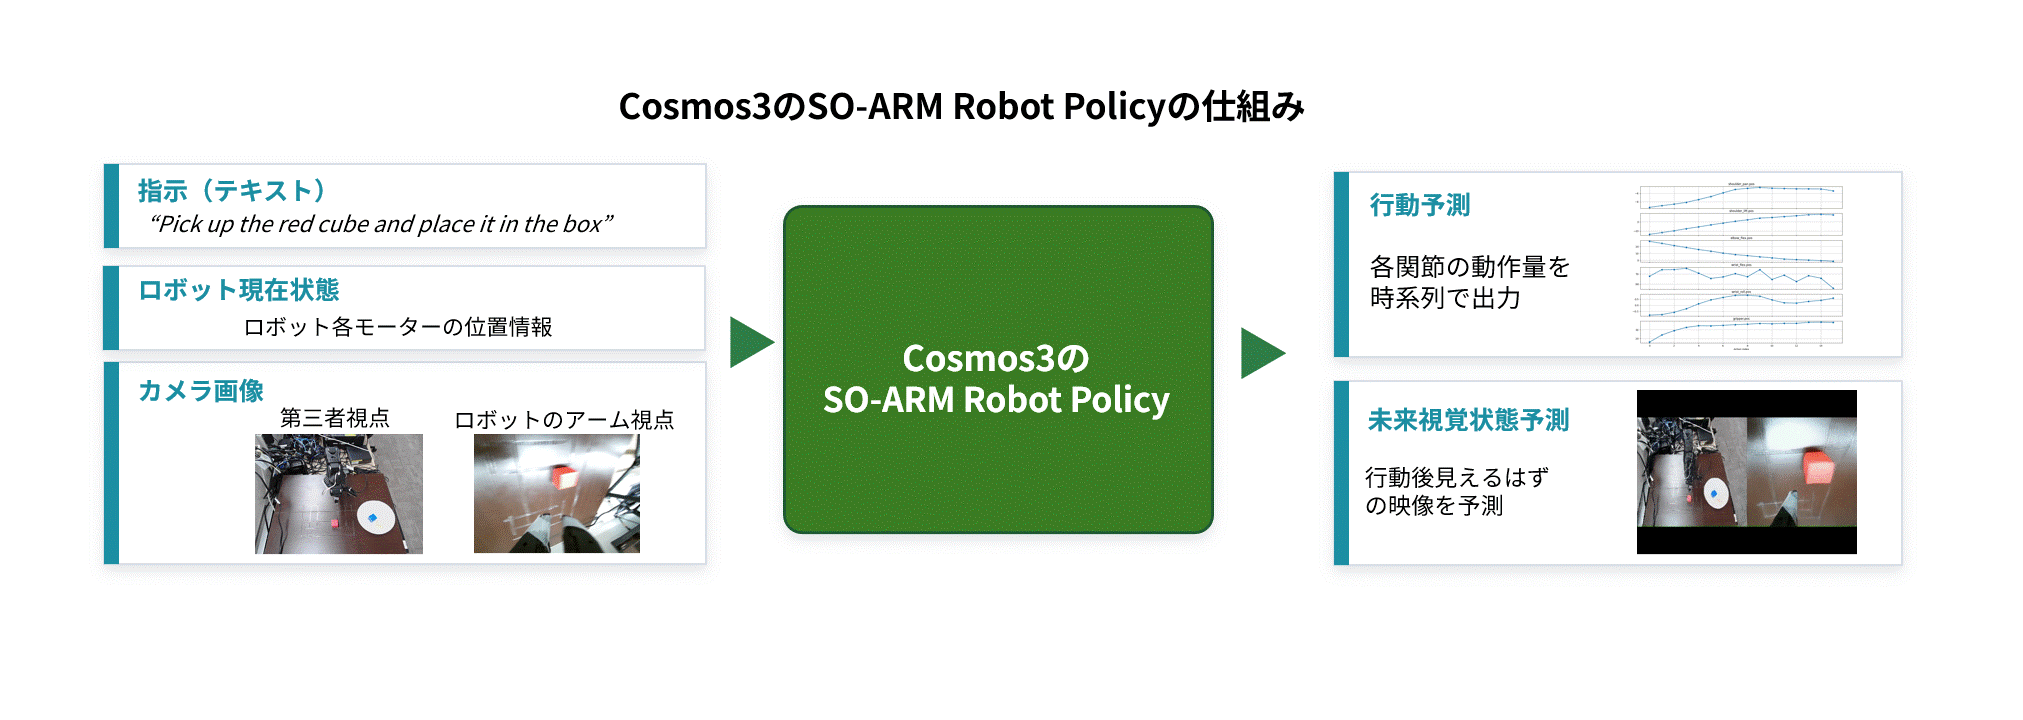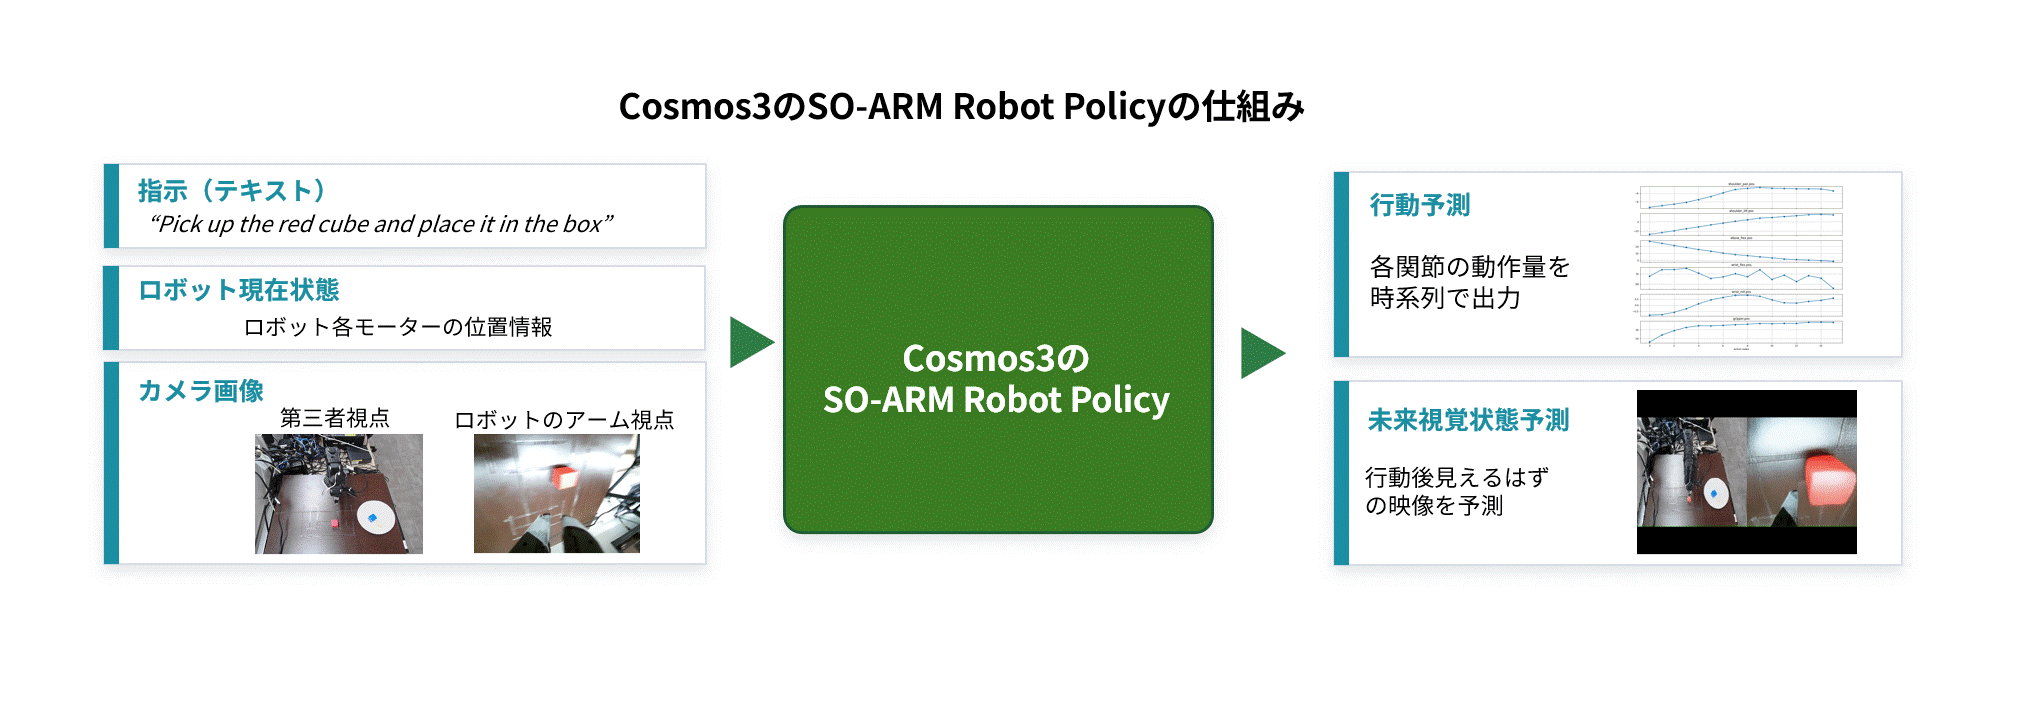
On the other hand, Cosmos 3's Robot Policy does more than simply generate actions. It predicts movements based on the robot's state and verbal instructions. Furthermore, a key feature is its ability to simultaneously predict the "future visual state"—how the surroundings will change after the robot moves.
In other words, while VLA is a model that "determines the next action based on the current situation," Cosmos 3's Robot Policy is a model that predicts "how the world will change as a result of the action" together with the action itself. Models that handle future states and actions simultaneously in this way are called World Action Models (WAMs).
Cosmos 3's Robot Policy is a model that can predictnot only the robot's actions but also "how the world will change as a result of those actions."
Cosmos 3 model lineup
Cosmos 3 offers multiple model sizes to suit different applications and execution environments. Larger models generally offer higher performance, but they also require more GPU resources for training and inference.
|
Model |
size |
Features |
Main uses |
|
Cosmos 3 Super |
64B |
The highest performance model |
High-precision synthetic data generation |
|
Cosmos 3 Nano |
16B |
A well-balanced model |
A good balance between speed and quality Robot control, video understanding, Synthetic data generation |
|
Cosmos 3 Edge |
4B |
Lightweight model |
Inference on edge devices, Robot embedded applications |
For this test, we used the Cosmos 3 Nano. This was because our goal was to verify the post-training recipes for Robot Policy that were publicly available at the time of testing, as well as to confirm the actual operation of the device. Note that the Cosmos 3 Edge, which is lighter than the Nano, is now also available in the lineup.
Reference: Cosmos3 Model Matrix
Verification Overview
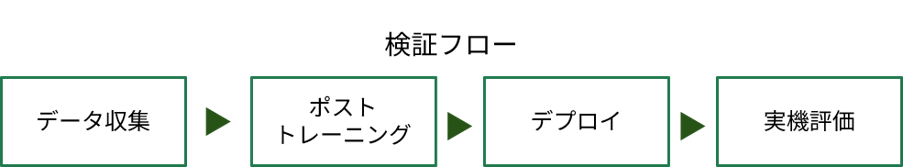
In this verification, we created a Robot Policy using SO-ARM operation data that we collected ourselves, referencing post-training recipes for Robot Policy published by NVIDIA, and then verified its operation on a real robot.
The purpose of this verification is to construct a Robot Policy using publicly available recipes and to confirm that the Robot Policy generated through post-training can be used for actual robot control.
Furthermore, Robot Policy is not a model specific to any particular robot. Based on Cosmos 3, Robot Policy can be built for different robots by performing post-training using the operation data of each robot. In this case, we created a Robot Policy for SO-ARM, but it is expected that it can be applied to other robots using a similar approach.
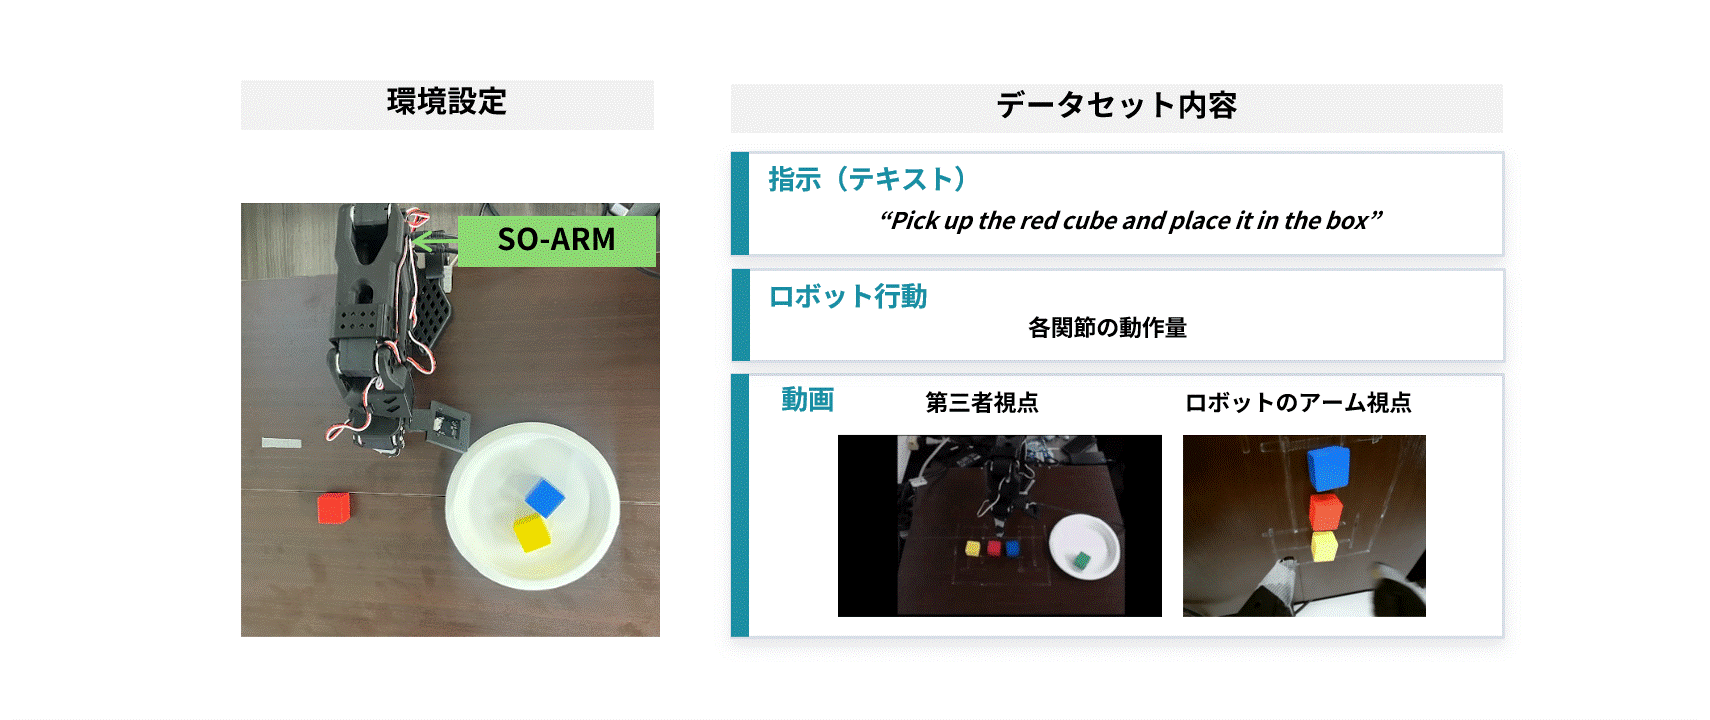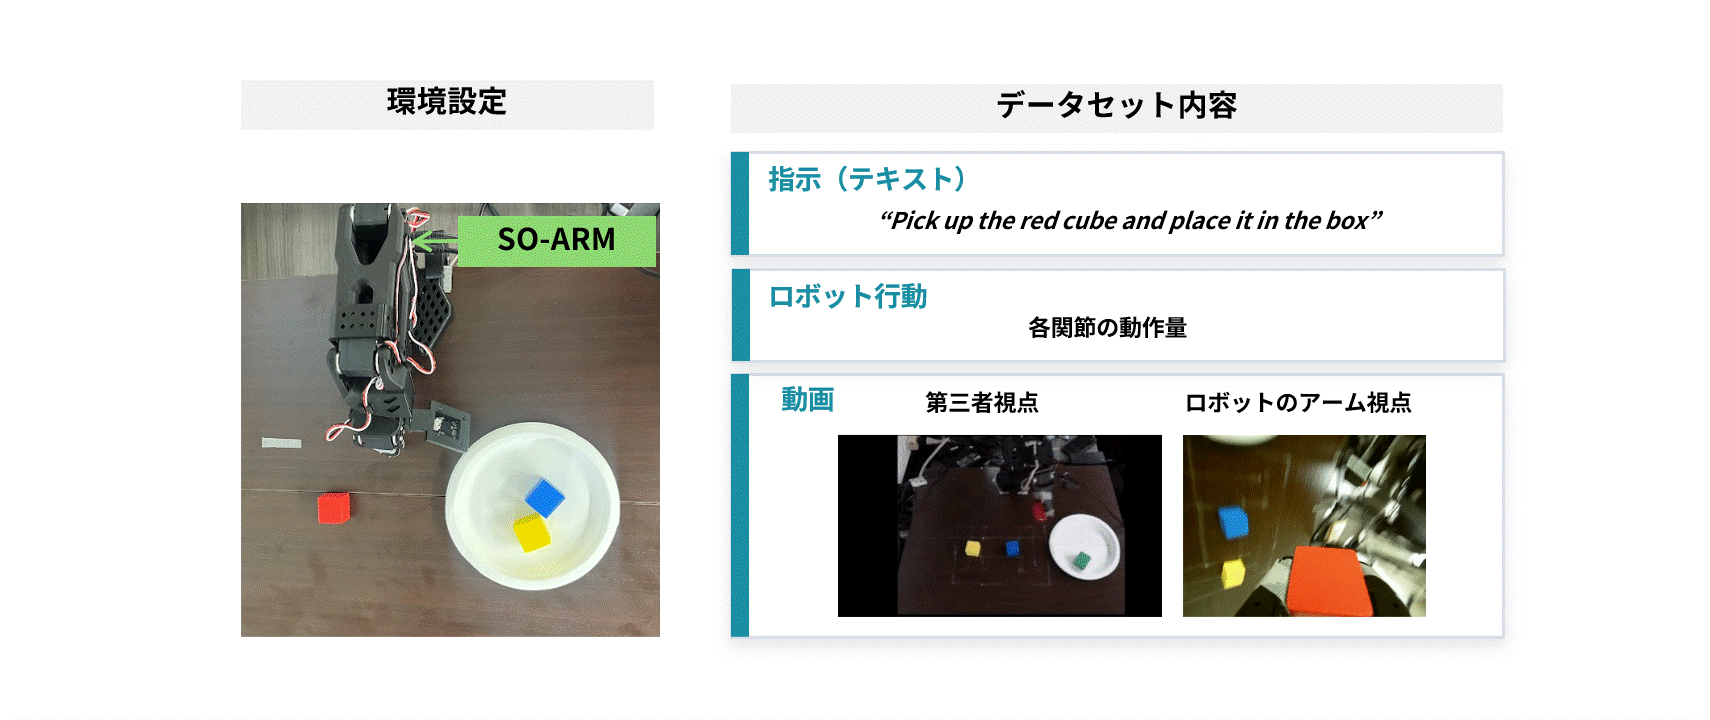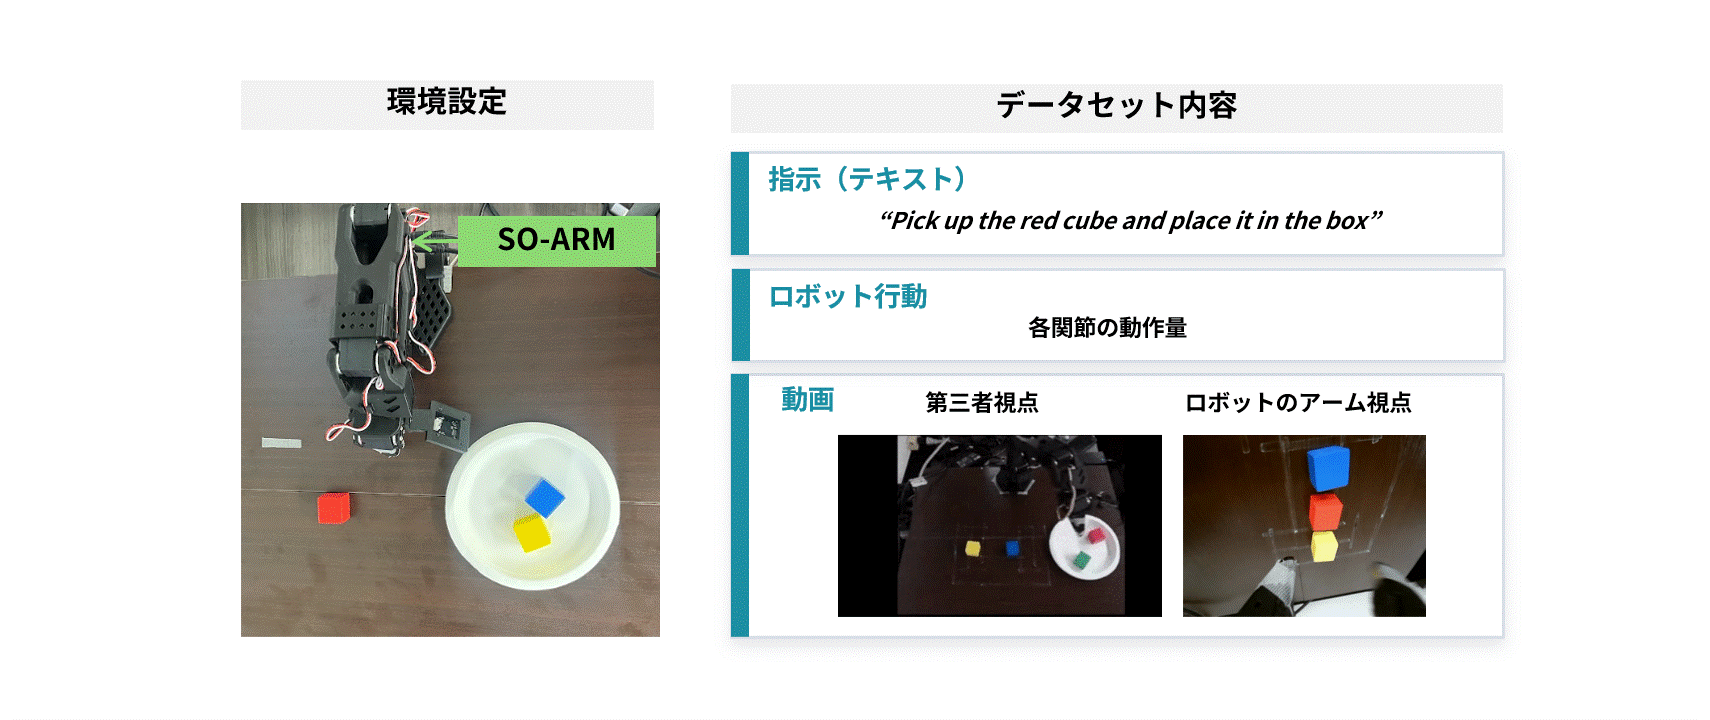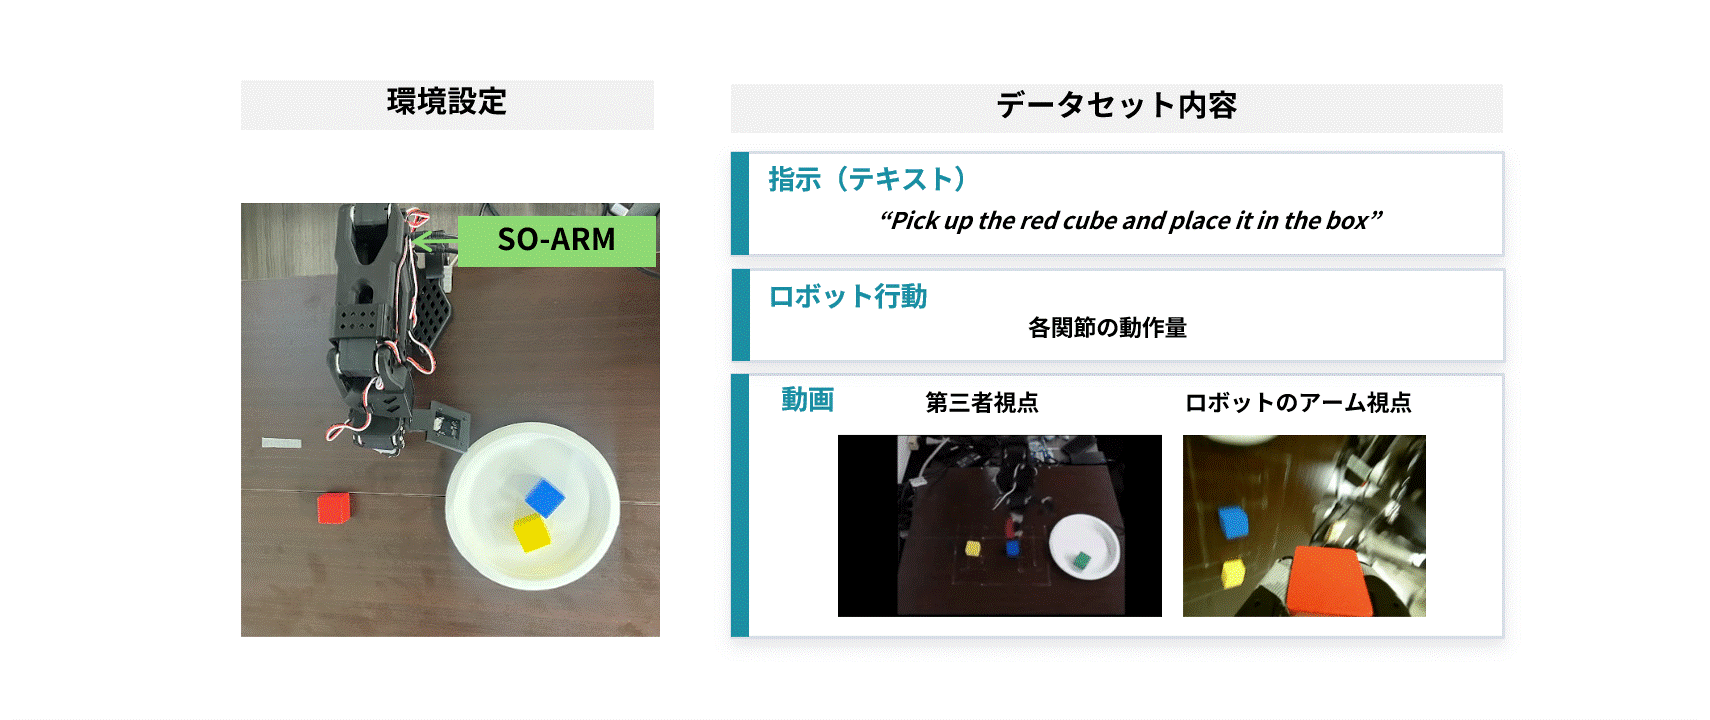
Dataset
The learning task used was a Pick & Drop task, where the robot had to pick up a cube of a specified color and move it to a designated position. We operated SO-ARM to collect data for 132 episodes. Each episode included work instructions, two-view camera footage, the robot's joint status, and the actual actions performed.
Verification environment
|
item |
content |
|
OS |
Ubuntu 24.04 |
|
GPU |
NVIDIA GB200 NVL72 (KDDI provided environment) |
|
Model |
nvidia/Cosmos3-Nano |
For this verification, we used the NVIDIA GB200 environment on KDDI GPU Cloud. The GB200 is a very high-performance GPU that can also be used for training large-scale AI models.
Reference: KDDI GPU Cloud
Post-training deployment
To use Cosmos 3-Nano with SO-ARM, post-training was performed using the collected data. The training settings reflected the number of joints in SO-ARM, camera configuration, and output action format. After training, the created checkpoints were placed on the Robot Policy server, creating a configuration that allows images and robot status to be sent from the actual robot client.
Reference: cosmos-framework/ action_policy_libero_posttrain
cosmos-framework/action_policy_droid_posttrain
Inference and robot control using actual machines
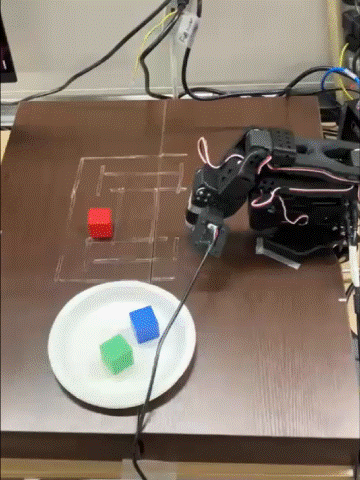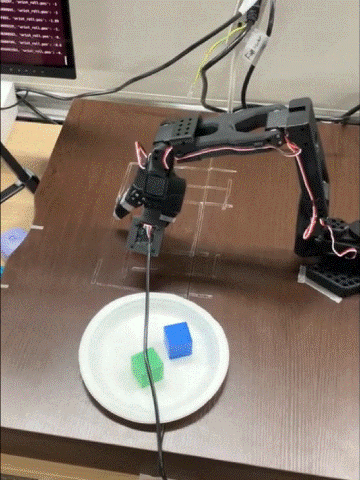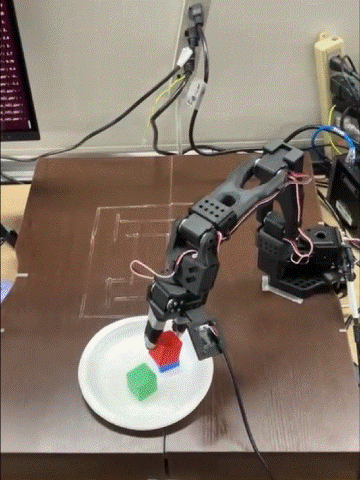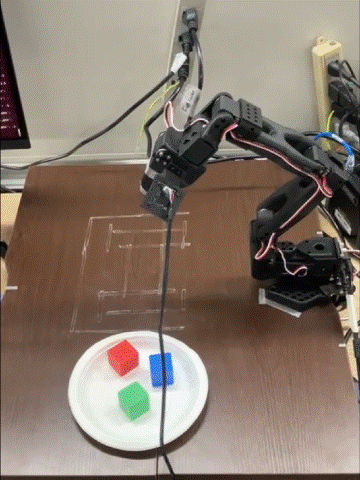
During execution, the SO-ARM sends the current camera image, joint status, and verbal commands to the Robot Policy server. The Robot Policy then controls the actual robot by returning the predicted joint movements to the SO-ARM.
The SO-ARM robot is controlled to perform the predicted actions.
Reference: cosmos-framework/action_policy_droid_server
My impressions after trying it
What I found particularly interesting about Cosmos 3's Robot Policy was its ability to not only predict the next action but also to handle future visual states simultaneously.
This characteristic has the potential to expand into the following applications in the future:
- Expanding the training data
- Confirmation of changes in state and risks before execution
This verification was the first step in confirming the entire process of post-training Cosmos 3 for a custom robot and connecting it to the actual robot.
Summary
This article provided an overview of Robot Policy development using Cosmos 3, from data collection to post-training, deployment, and real-world testing.
The key points are as follows:
・Cosmos 3 is, Physical AI Base model for
Cosmos 3's Robot Policy predicts both behavior and future states simultaneously. WAM
・Use publicly available recipes to create your own Robot Policy We were able to build it and verify its operation with an actual robot.
We hope this article will be helpful when considering the development of Robot Policy using Cosmos 3, the construction of a learning environment for Physical AI, and its application to actual robots.
Contact Us
If you are considering implementing Physical AI or have any questions regarding building a learning environment, please feel free to contact us.