- Semiconductor BusinessHOME
- Products and Services of Macnica,Inc.
-
technical information

-
Events and Seminars
- Handling Manufacturer
- Support
- Inquiry
- Click here to purchase products
- Semiconductor business e-mail magazine registration


 Narrow down by specifying conditions
現在2228件がヒットしています。check
"We want to fully implement AI agents. How many GPUs will we need?"
This is a frequently asked topic, but it's a difficult question to answer.
While excellent models are being released one after another, optimization and inference acceleration technologies are also being developed, leaving us wondering, "How many GPUs do I actually need?" The number of GPUs required varies greatly depending on the tasks assigned to the agents and the number of users, so it's impossible to say definitively, "This many is enough." As a result, many people struggle to decide on GPU investment decisions. This article will provide a rough guideline from the perspective of "how many GPUs are needed for how many users."
Why do AI agents need GPUs?
It's a common misconception, but the agent itself runs on the CPU.
The GPU is needed for the part of the loop where the agent executes the LLM, which is responsible for "thinking." The agent doesn't think on its own; it queries the LLM every time it thinks.
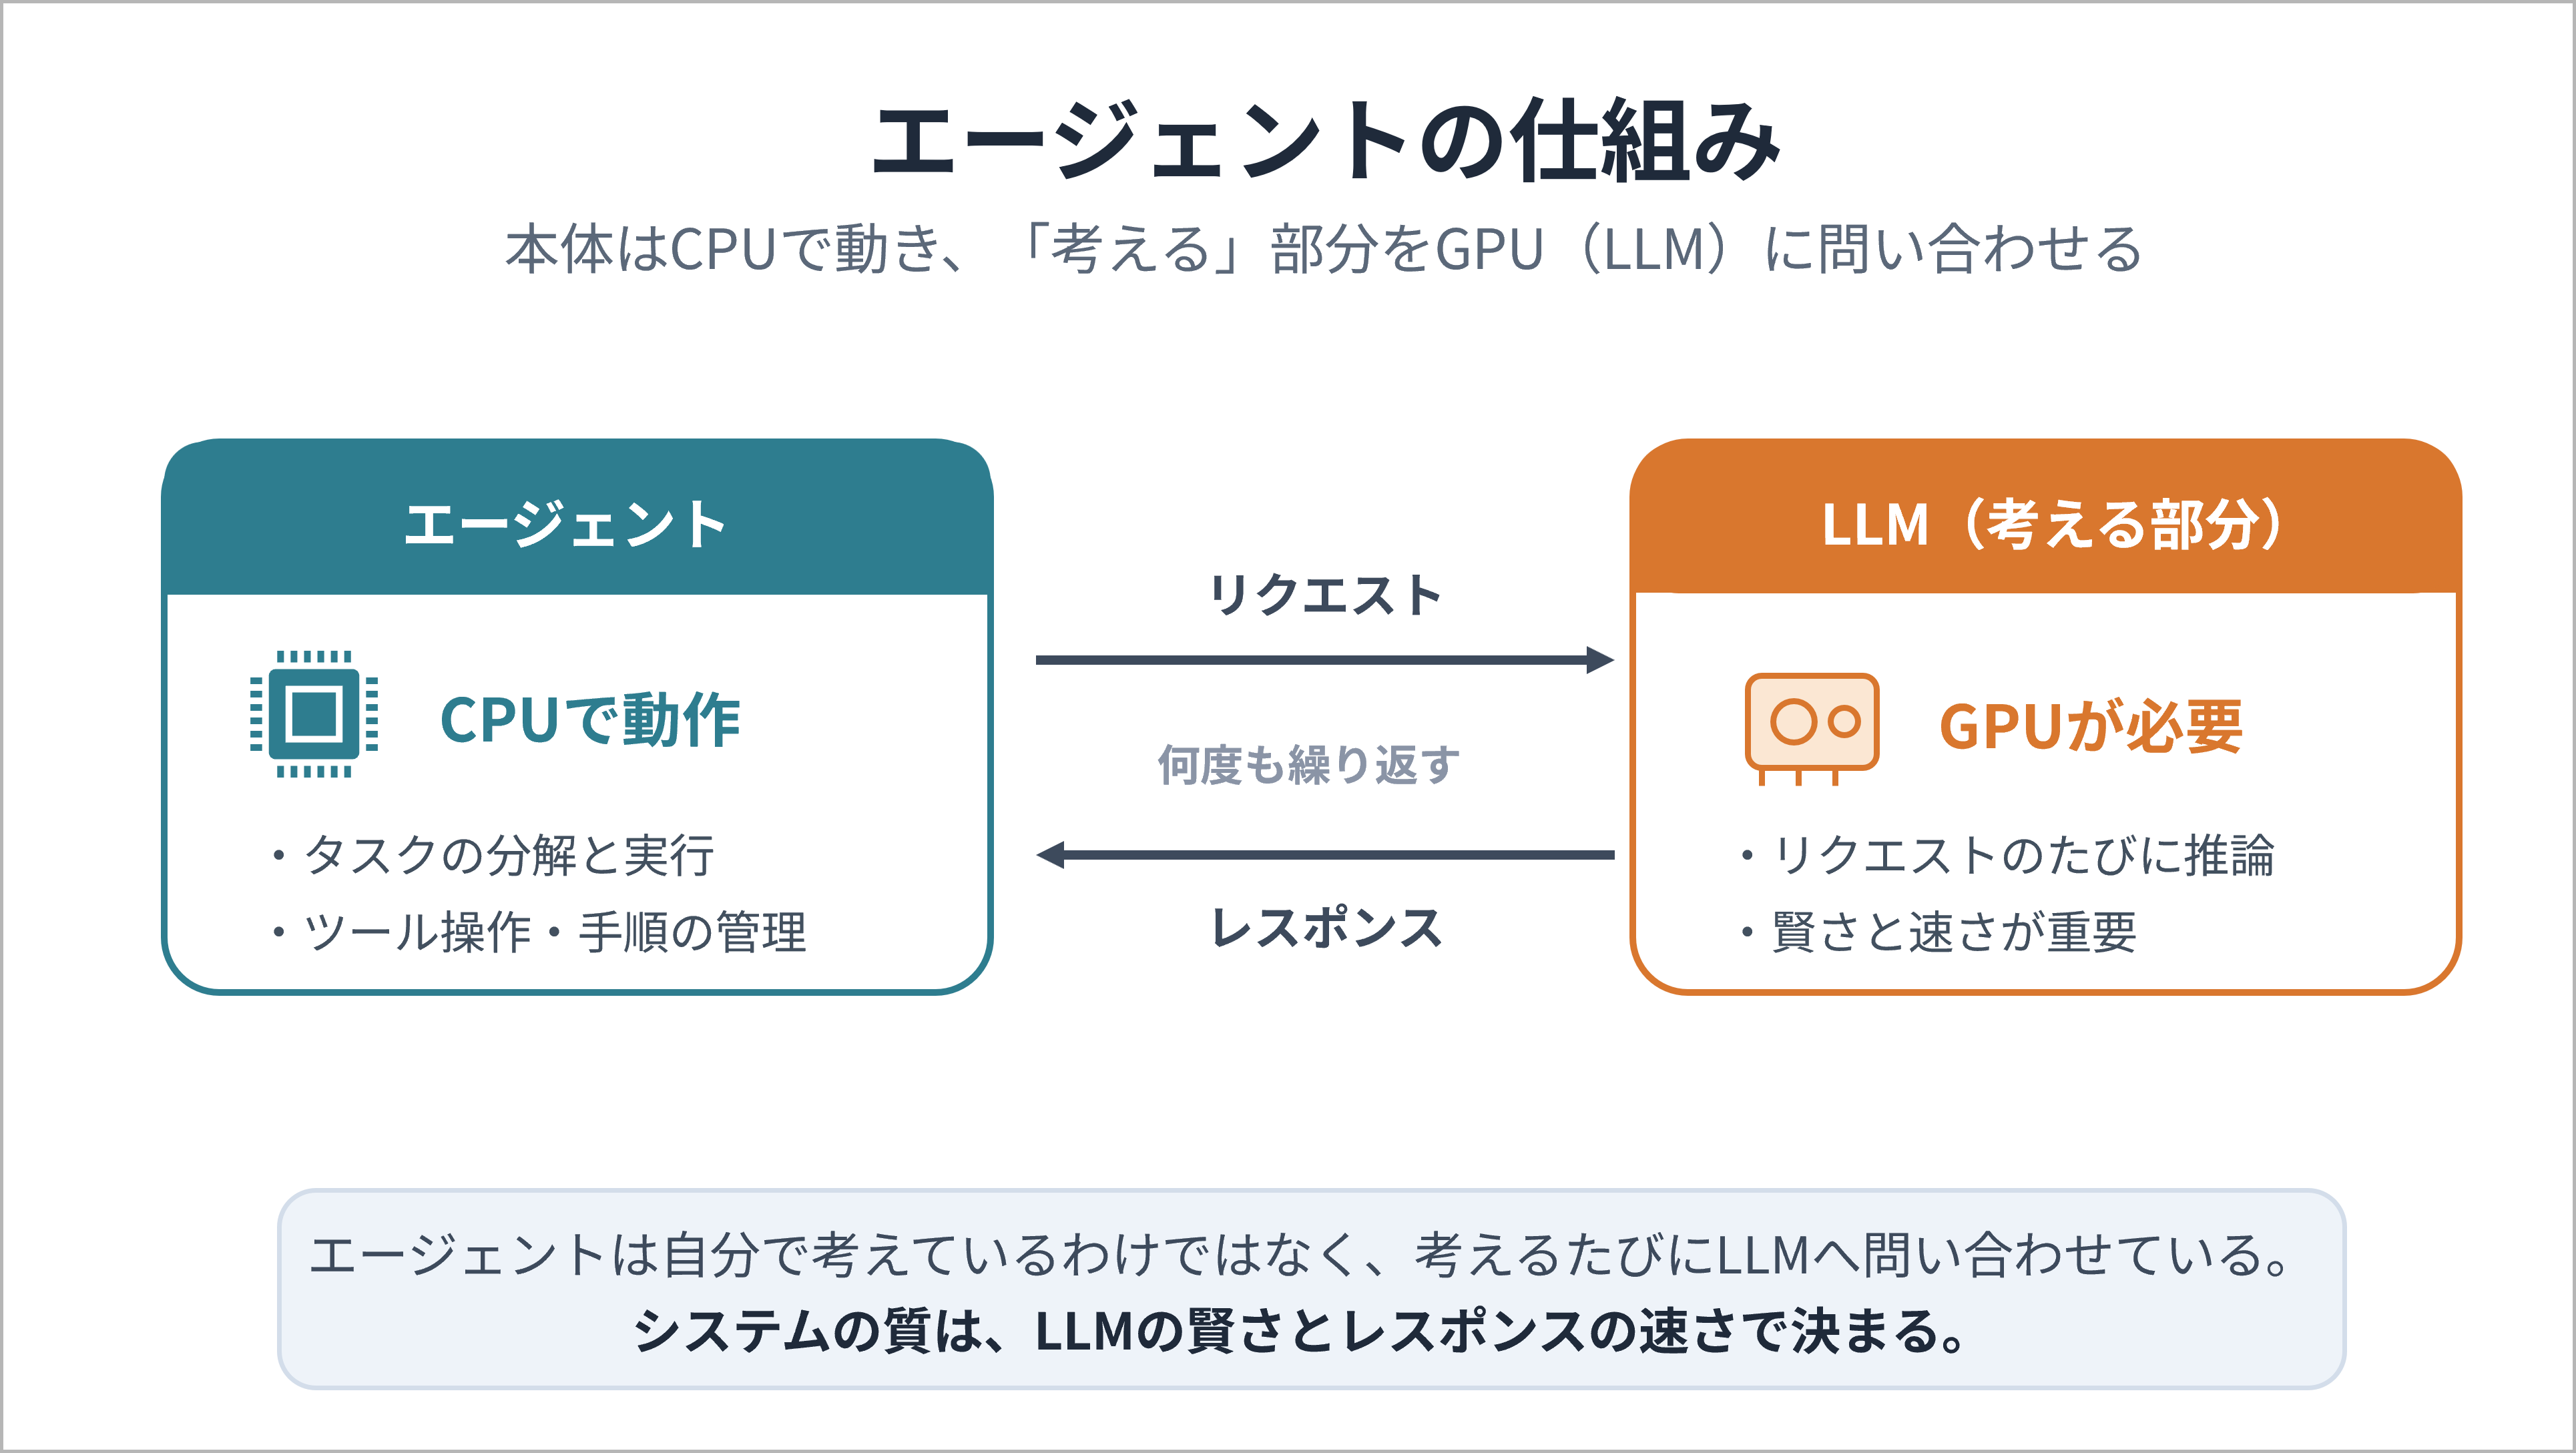
While the development of agents (harnesses) certainly has an impact, the majority of factors that determine the overall quality of the agent system are determined by the intelligence and responsiveness of the LLM.
GPU requirements based on the number of simultaneous users
This time, we will consider the number of GPUs needed for each user, assuming the following scenario.
|
item |
explanation |
| model | nvidia/Kimi-K2.7-Code-NVFP4 |
| Number of parameters | Total parameters 1T, active 32B |
| Tasks to request from an agent | Coding, data collection from PDFs and the web |
| Request for a quick response | It doesn't feel slow. |
| Number of simultaneous users | 1-100 people |
The Kimi K2.7 employs a MoE architecture, which, despite having a large total number of parameters, uses fewer weights during inference, resulting in high-speed operation. Furthermore, by adopting a quantized model called NVFP4 developed by NVIDIA, it is optimized for faster operation while minimizing GPU memory usage, making it an ideal model for agents. It has achieved excellent results in various benchmarks, and I personally believe its performance is comparable to commercial models.
The requirement for response speed is vaguely stated as "not slow in terms of feel," but quantifying this is extremely difficult. A common metric is tok/s (how many tokens can be generated per second), and in my experience, a response of around 100 tok/s feels fast.
How to think about GPU requirements
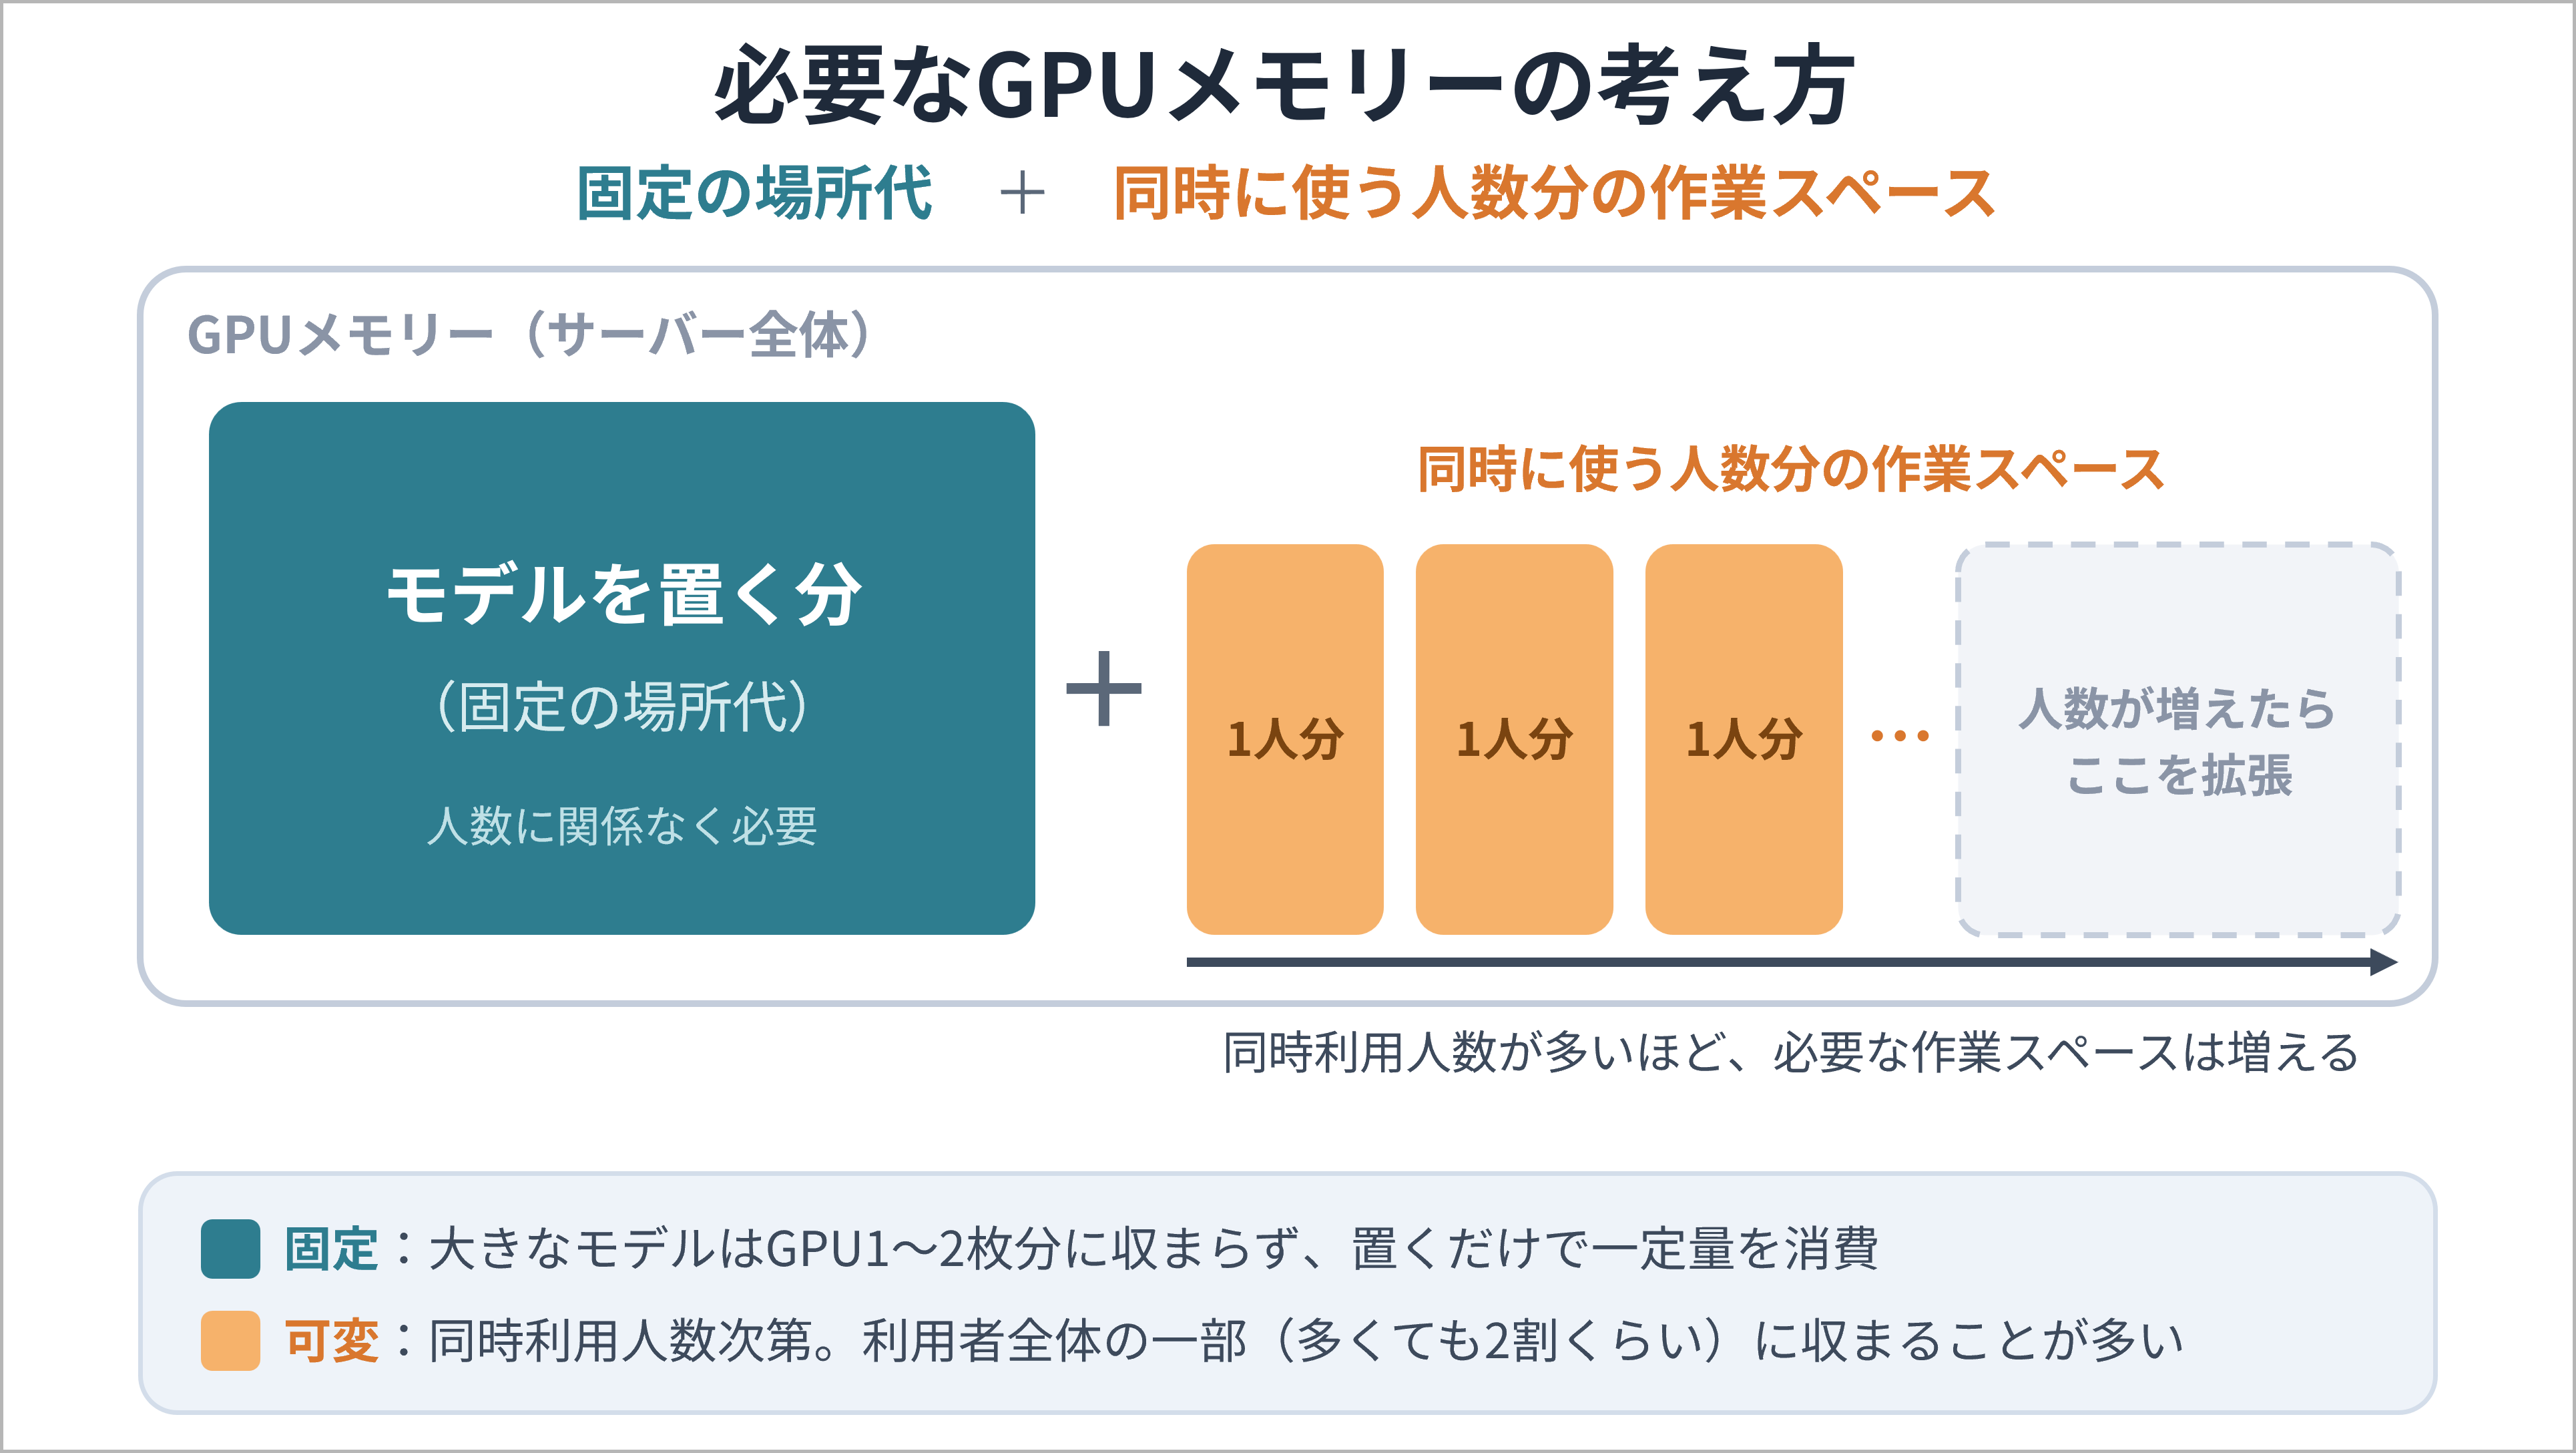
Now that we've finished explaining the case, let's consider the main topic: the required amount of GPU. Roughly speaking, the amount of GPU needed is determined by the sum of "GPU memory for storing the model" and "GPU memory for users to work on simultaneously."
- GPU memory for storing models: This is a fixed space fee that is required regardless of the number of users. Large models like the Kimi K2.7 generally cannot fit on one or two GPUs.
• GPU memory for simultaneous user work: The more people using it simultaneously, the more additional workspace is needed for each person. (This is known as KV cache.)
The important point here is that "number of simultaneous users" is different from "number of users."
Even in a team of 100 people, not everyone presses the button at the same moment. In reality, the number of people simultaneously contacting the AI is usually only a fraction of all users.
Based on this premise, let's look at the guidelines for different numbers of simultaneous users.
🔷Number of simultaneous users: 1 to 5 people
At first, it's at the stage of "I want to try it out" or "I want to use it with some members."
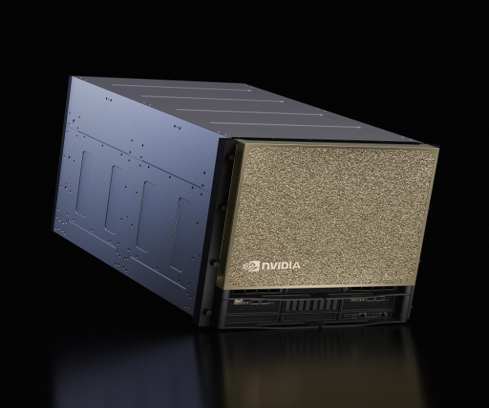
For this scale, one server equipped with eightNVIDIA DGX™ B200 graphics cards would be a good starting point.
Even a large model like the Kimi K2.7 can easily accommodate a configuration with eight B200 chips, and this single machine can comfortably handle usage by 1 to 5 people. In fact, it might even seem like overkill for 5 people. However, think of this as a starting point—"if you're going to run a large model in-house, this is the minimum configuration you need." It's more realistic to start with this configuration and then move on to the next stage as the number of users increases.
🔷Number of simultaneous users: 5 to 20 people
This is the stage where everyone in the team or department uses it to some extent in their daily work.
At this scale, you'll want a configuration with more headroom. A good guideline would be a server with eightNVIDIA DGX™ B300 graphics cards, each with more memory than the B200.
Even with the same 8 cards, having extra memory means that even if more people use it simultaneously, each person can have ample workspace. The key point at this stage is to ensure there is enough extra memory not only for the models but also for the number of simultaneous users.
🔷20 to 100 simultaneous users
This is the stage where we are rolling it out company-wide and ensuring stable operation as a production service.
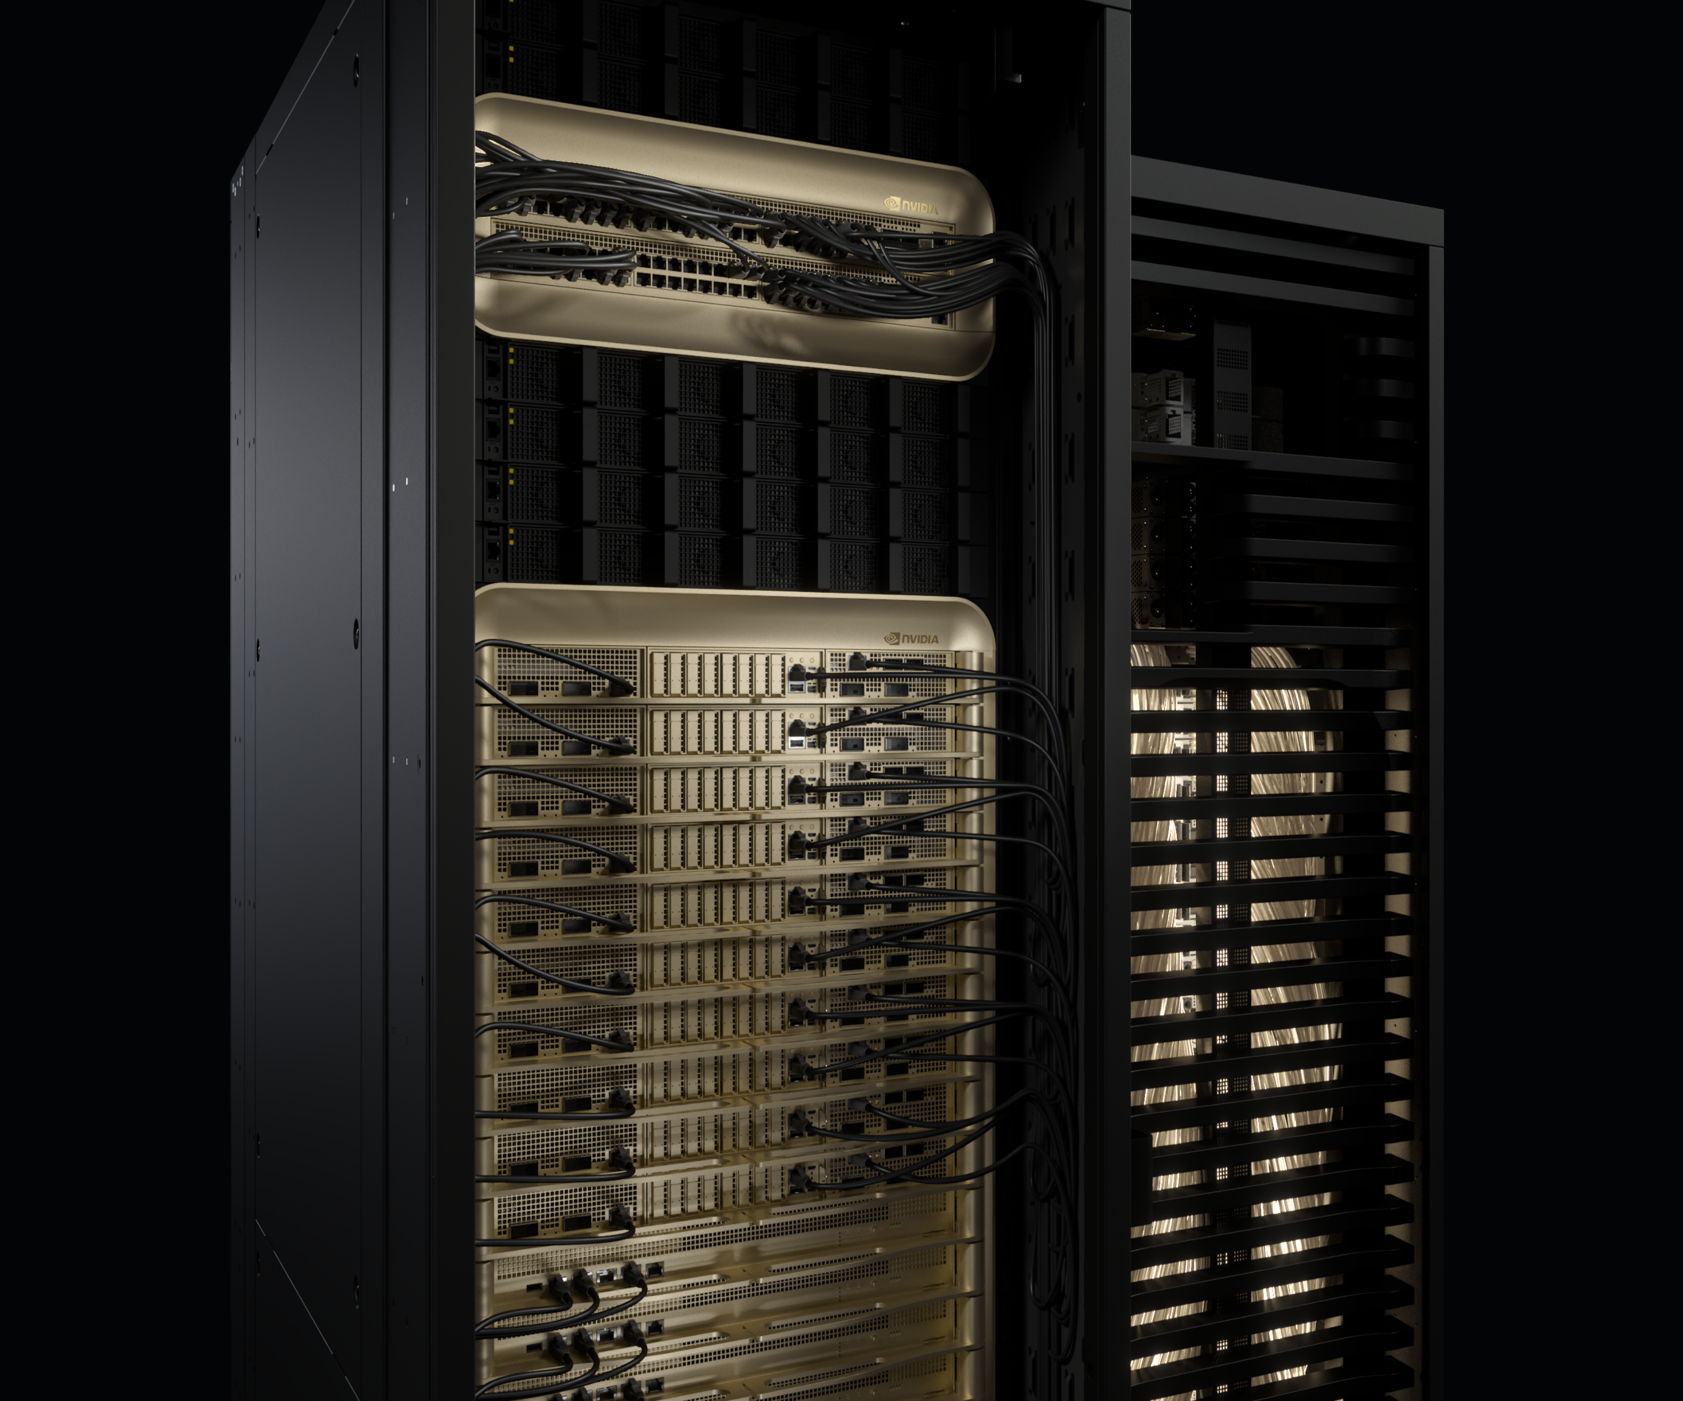
At this point, one server is no longer sufficient; you'll need multiple servers equipped withNVIDIA DGX™ B300, or a large-scale configuration with them connected at high speed (like a cluster such as the NVIDIA GB300 NVL72).
At this scale, the number of GPUs required depends on "how many more people will be using it simultaneously," so it's common practice to increase the number of servers while monitoring actual usage.
It's best not to make a final decision based solely on theoretical calculations, but rather to test it out using the intended application.
Summary
To summarize, the number of GPUs required is determined by the sum of "GPU memory for storing the model (fixed)" and "GPU memory for users to work on simultaneously." If you plan to run large models in-house, you will need a certain scale from the start.
|
Number of simultaneous users |
Usage Image |
Guidelines for GPU configuration |
| 1-5 people | Trial use, available to some members | One unit containing 4-8 B200 units (such as DGX B200 ). |
| 5-20 people | Daily use by teams and departments | One unit of B300 x 8 (such as DGX B300) |
| 20-100 people | Company-wide deployment and production service | Multiple B300 x 8 units ~ GB300 NVL72 cluster |
You don't need to aim for perfect scale from the start. It's more realistic to start small and then increase the number of servers as the number of users grows.
※supplement:
The structure of this article is merely a guideline. In reality, even if the number of users increases and there is insufficient GPU memory for simultaneous work, LLM can continue to run by techniques such as temporarily moving the KV cache to CPU memory (however, this will result in slower response times).
Furthermore, in actual operation, there are many other factors to consider, such as the type of model and the size of the context.
Since the required GPU may change with future updates, we recommend not making a decision based solely on theoretical calculations, but rather determining it through actual use.
Contact Us
Macnica provides support for the implementation of local LLMs and agents. Please contact us if you are interested.
Related product page